Note
Go to the end to download the full example code.
Gradient spoiling#

The gradient echo of the previous section leaves transverse magnetisation at the end of each repetition, and the following pulses refocus part of it. This lesson adds a spoiler gradient after the acquisition. The spoiler dephases the remaining transverse magnetisation through several cycles across a voxel, so that it integrates to nearly zero there; because every repetition applies the same dephasing, a coherent pathway remains and contributes to the steady state.
The steady-state signal is computed by summing isochromats across a voxel over several hundred repetitions of the sequence built here, and compared with the signal of an ideally spoiled repetition. The next lesson, RF spoiling, suppresses the coherent pathway that gradient spoiling leaves.
Learning objectives#
After this lesson, you should be able to:
prescribe a spoiler gradient by its dephasing across a voxel and place it in the repetition;
compute a steady-state signal by an isochromat summation that uses the echo time, repetition time and spoiler area of the built sequence;
relate the steady-state signal to the spoiler area and to the flip angle;
explain why no spoiler area reproduces the ideally spoiled signal.
The spoiler#
The prescription is the same gradient echo, with one gradient added after the acquisition. A spoiler is stated as the phase it winds across a voxel, and the voxel here is the in-plane sample spacing of the prescription.
import numpy as np

import pypulseqpp as pp

system = pp.Opts(
    max_grad=32.0,
    grad_unit="mT/m",
    max_slew=130.0,
    slew_unit="T/m/s",
    rf_dead_time=100e-6,
    rf_ringdown_time=20e-6,
    adc_dead_time=10e-6,
)

FOV = 220e-3
MATRIX = 128
THICKNESS = 5e-3
FLIP_ANGLE_DEG = 12.0
REPETITION_TIME = 20e-3
SPOILER_CYCLES = 4.0

VOXEL = FOV / MATRIX

rf, gz, gz_reph = pp.make_sinc_pulse(
    flip_angle=np.deg2rad(FLIP_ANGLE_DEG),
    duration=2e-3,
    slice_thickness=THICKNESS,
    apodization=0.5,
    time_bw_product=4.0,
    delay=system.rf_dead_time,
    system=system,
    use="excitation",
    return_gz=True,
)

dwell, readout_time = pp.calc_adc_timing(
    MATRIX,
    26e-6,
    grad_raster_time=system.grad_raster_time,
    adc_raster_time=system.adc_raster_time,
)
gx = pp.make_trapezoid(
    channel="x", flat_area=MATRIX / FOV, flat_time=readout_time, system=system
)
adc = pp.make_adc(num_samples=MATRIX, dwell=dwell, delay=gx.rise_time, system=system)
gx_pre = pp.make_trapezoid(channel="x", area=-gx.area / 2, duration=1e-3, system=system)
gy_pre = pp.make_trapezoid(
    channel="y", area=MATRIX / (2 * FOV), duration=1e-3, system=system
)
One repetition#
The spoiler is played on the slice axis after the acquisition, where it dephases the transverse magnetisation the repetition leaves behind without adding to the k-space the readout traverses. It lengthens the repetition, so the delay that brings the repetition up to the repetition time absorbs less.
def gradient_spoiled(cycles, flip_angle_deg=FLIP_ANGLE_DEG):
    """The sequence, with a spoiler of the given dephasing across a voxel."""
    pulse, selection, rephaser = pp.make_sinc_pulse(
        flip_angle=np.deg2rad(flip_angle_deg),
        duration=2e-3,
        slice_thickness=THICKNESS,
        apodization=0.5,
        time_bw_product=4.0,
        delay=system.rf_dead_time,
        system=system,
        use="excitation",
        return_gz=True,
    )
    spoiler = pp.make_crusher(cycles, VOXEL, channel="z", system=system)[0]
    played = (
        pp.calc_duration(pulse, selection)
        + pp.calc_duration(gx_pre, gy_pre, rephaser)
        + pp.calc_duration(gx, adc)
        + pp.calc_duration(spoiler)
    )
    seq = pp.Sequence(system=system)
    for step in np.linspace(-1.0, 1.0, MATRIX, endpoint=False):
        seq.add_block(pulse, selection)
        seq.add_block(gx_pre, pp.scale_grad(gy_pre, step), rephaser)
        seq.add_block(gx, adc)
        seq.add_block(spoiler)
        seq.add_block(
            pp.make_delay(
                pp.round_to_raster(
                    REPETITION_TIME - played, system.block_duration_raster
                )
            )
        )
    return seq


seq = gradient_spoiled(SPOILER_CYCLES)

ok, errors = seq.check_timing()
spoiler_duration = pp.calc_duration(
    pp.make_crusher(SPOILER_CYCLES, VOXEL, channel="z", system=system)[0]
)
print(
    f"timing {ok}, {seq.num_blocks} blocks, "
    f"spoiler {1e3 * spoiler_duration:.2f} ms for {SPOILER_CYCLES:.0f} cycles "
    f"across a {1e3 * VOXEL:.2f} mm voxel"
)

seq.paper_plot(tr=1)
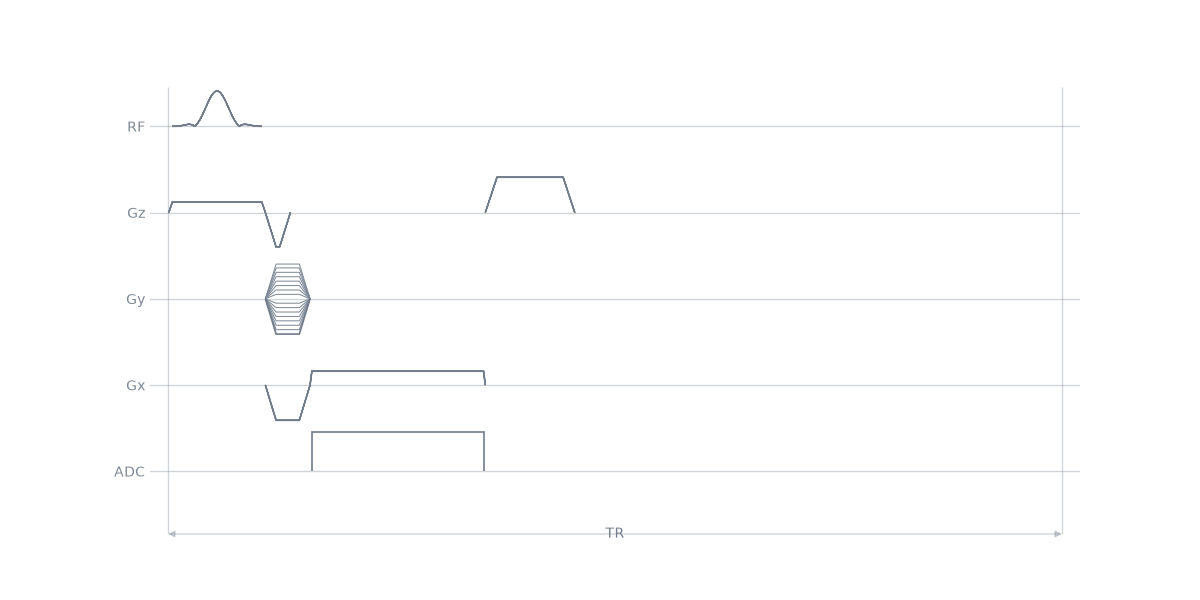
timing True, 640 blocks, spoiler 2.00 ms for 4 cycles across a 1.72 mm voxel
Isochromats across a voxel#
The steady state is reached by playing the repetition several hundred times on a set of isochromats spread across one voxel. Each one has a complex transverse component and a longitudinal one, and each repetition applies the pulse, the interval to the echo, the interval from the echo to the end of the repetition, and the phase the spoiler winds at that isochromat’s position.
The echo time and the repetition time come from the sequence that was built, and the spoiler phase from the dephasing it was prescribed with, so the summation follows the design rather than a restatement of it.
ISOCHROMATS = 201

_, _, t_excitation, _, t_adc = seq.calculate_kspacePP(block_range=[1, 5])
ECHO_TIME = float(t_adc[MATRIX // 2] - t_excitation[0])

print(
    f"echo time {1e3 * ECHO_TIME:.2f} ms, repetition time {1e3 * REPETITION_TIME:.2f} ms"
)


def steady_state(cycles, flip_angle_deg, t1=1000e-3, t2=80e-3, repetitions=600):
    """The signal the repetition settles at, summed across a voxel."""
    flip = np.deg2rad(flip_angle_deg)
    position = (np.arange(ISOCHROMATS) + 0.5) / ISOCHROMATS
    spoiler_phase = np.exp(2j * np.pi * cycles * position)

    transverse = np.zeros(ISOCHROMATS, dtype=complex)
    longitudinal = np.ones(ISOCHROMATS)
    signal = np.zeros(repetitions, dtype=complex)

    for repetition in range(repetitions):
        # The pulse, about an axis in the transverse plane.
        rotated = (
            np.cos(flip / 2) ** 2 * transverse
            + np.sin(flip / 2) ** 2 * np.conj(transverse)
            - 1j * np.sin(flip) * longitudinal
        )
        longitudinal = np.cos(flip) * longitudinal + np.sin(flip) * np.imag(transverse)
        transverse = rotated

        # Excitation to echo, where the signal is read.
        transverse *= np.exp(-ECHO_TIME / t2)
        longitudinal = 1.0 + (longitudinal - 1.0) * np.exp(-ECHO_TIME / t1)
        signal[repetition] = transverse.mean()

        # Echo to the end of the repetition, and the spoiler.
        rest = REPETITION_TIME - ECHO_TIME
        transverse *= np.exp(-rest / t2) * spoiler_phase
        longitudinal = 1.0 + (longitudinal - 1.0) * np.exp(-rest / t1)

    return signal


def ideally_spoiled(flip_angle_deg, t1=1000e-3):
    """The signal of a repetition that begins with no transverse component."""
    flip = np.deg2rad(flip_angle_deg)
    recovery = np.exp(-REPETITION_TIME / t1)
    return np.sin(flip) * (1 - recovery) / (1 - recovery * np.cos(flip))
echo time 4.05 ms, repetition time 20.00 ms
Steady state against spoiler area#
The sweep is run at the prescribed flip angle and at one large enough for the residual pathway to be substantial.
CYCLES = np.linspace(0.0, 8.0, 41)
SWEPT_FLIPS = (FLIP_ANGLE_DEG, 30.0)

against_area = {
    flip: np.array([abs(steady_state(cycles, flip)[-1]) for cycles in CYCLES])
    for flip in SWEPT_FLIPS
}
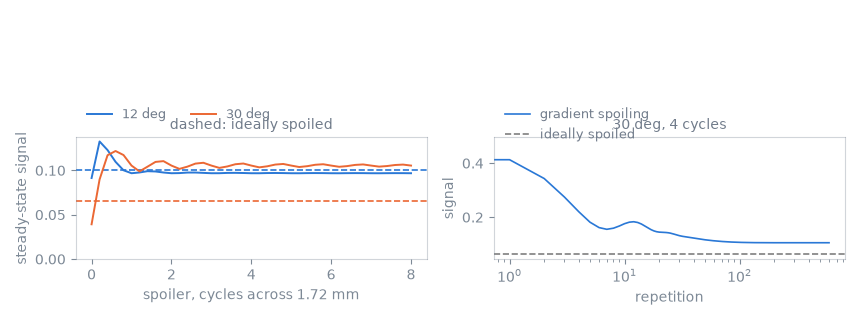
at 30 degrees: ideally spoiled 0.0655, gradient spoiled 0.1054, rippling by 4.7 percent above three cycles
Below one cycle across a voxel the isochromats are not spread over the whole circle, and the steady state depends on how far the spoiler winds them. Above it the dependence is a ripple that decays as the reciprocal of the cycle count, because a uniform voxel wound through a non-integral number of cycles does not quite average to zero, and past about three cycles the curve is flat to the last digit.
The plateau consists of a pathway that the pulse refocuses from one repetition to the next: the spoiler winds every repetition through the same phase, so it leaves that pathway unchanged. At 30 degrees that residual is more than one and a half times the ideally spoiled signal it is being compared with, and no spoiler area removes it.
The right-hand panel shows the approach to the steady state at the prescribed spoiler, which takes a few hundred repetitions — long enough that the first lines of a scan are acquired before it.
Steady state against flip angle#
The residual pathway contains magnetisation that the pulse returns from the longitudinal axis, so it grows with the flip angle, and it adds to or subtracts from the ideally spoiled signal depending on where the flip angle sits.
FLIP_ANGLES = np.arange(2.0, 61.0, 2.0)

by_flip = np.array(
    [abs(steady_state(SPOILER_CYCLES, flip)[-1]) for flip in FLIP_ANGLES]
)
by_flip_ideal = ideally_spoiled(FLIP_ANGLES)
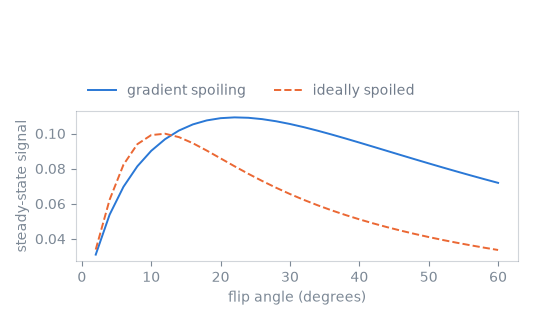
 flip   gradient spoiled   ideally spoiled   ratio
   10             0.0901            0.0991    0.91
   20             0.1087            0.0858    1.27
   30             0.1054            0.0655    1.61
   40             0.0948            0.0511    1.86
   50             0.0830            0.0410    2.02
   60             0.0719            0.0336    2.14
peak: ideally spoiled at 12 degrees, gradient spoiled at 22 degrees
The ideally spoiled curve peaks at the Ernst angle for this repetition time and T1, and its shape is what a signal model inverted for T1 assumes. The gradient-spoiled curve peaks well beyond it, falls below it at small flip angles and rises to twice it at large ones, and the whole departure depends on T2, which that model does not include. The RF phase cycle of the next lesson reduces this dependence.
Total running time of the script: (0 minutes 2.327 seconds)