

Note
Go to the end to download the full example code.
Staged training of an unrolled network#

Aim. Train an unrolled reconstruction network for fourfold undersampled, eight-channel Cartesian brain data within the memory of one iteration, and show that it removes the residual aliasing and the g-factor noise that CG-SENSE leaves at this acceleration.
An unrolled network alternates data consistency with a learned regularizer for a fixed number of iterations. Here the iteration is BART’s iterative soft thresholding with the thresholding replaced by a convolutional network \(D_\theta\),
where \(A\) is the SENSE encoding (coil sensitivities, Fourier transform, sampling mask) and \(\tau\) a learned step size. One set of network weights serves every iteration. The iteration index \(k\) enters the network by feature-wise modulation (FiLM), so that the same weights remove the strong incoherent aliasing of the first iterates and the fine residual noise of the last.
Training the stack end to end stores the activations of every iteration for the backward pass; for a 3D volume, or a series of them, that exceeds a single GPU. Urman et al. [1] reach the end-to-end result in three stages whose memory is bounded by one iteration:
Denoiser pretraining. The network alone learns to map degraded images to the fully sampled reference, each image tagged with the iteration index at which the unrolled iteration will meet that level of degradation.
Greedy training. Each iteration’s loss is back-propagated before the next iteration runs [2].
End-to-end fine-tuning. One loss on the final image, through the whole stack, with each iteration recomputed during the backward pass (gradient checkpointing) instead of stored.
bartorch.learning.Reconstruction runs each stage in
lightning; torchio holds and augments the training images.
Learning objectives
Condition a
bartorch.learning.UNeton the iteration index and pass the index to it throughbartorch.priors.ImplicitPrior.Train an unrolled
bartorch.optim.ISTBlockin the three stages ofbartorch.learning.Reconstruction.Split a dataset by subject and augment it with transforms that preserve the complex MR signal.
It follows Networks for complex volumes. The next lesson, Training without a reference, trains the same network without fully sampled references.
import csv
import logging
from pathlib import Path

import brainweb_dl
import lightning
import numpy as np
import torch
import torchio
from brainweb_dl import get_mri
from monai.metrics import PSNRMetric, SSIMMetric
from torch.utils.data import DataLoader

import bartorch
import bartorch.tools as bt
from bartorch import learning, linop, optim, priors

SIZE = 96
COILS = 8
ITERATIONS = 4
ACCELERATION = 4

_ = torch.manual_seed(0)
Images and acquisition#
Axial slices of two BrainWeb subjects, simulated as \(T_1\)-weighted spin-echo images (TR 600 ms, TE 12 ms) with a smooth background phase, as in MoDL, on BART’s ADMM. Training and validation are split by subject: no slice of subject 4 is trained on, so the validation scores measure how a network trained on one head generalizes to another. A random split of slices would place neighbouring, nearly identical slices of the same head on both sides and overstate the result.
The acquisition is an eight-channel receive array with Cartesian variable-density undersampling of the phase encodes at \(R = 4\), with a fully sampled centre of eight lines. Complex Gaussian noise of standard deviation 0.02 (relative to an image peak of one) is added to k-space, an SNR at which the unfolding of CG-SENSE amplifies the noise visibly.
train_images = brain_slices(subject=0, count=24)
valid_images = brain_slices(subject=4, count=8)

sensitivities = bt.coils(t=bt.grid(D=(SIZE, SIZE, 1)), n=COILS)[:, 0]
sensitivities = sensitivities / bartorch.rss(sensitivities, axes=(0,), keepdim=True)

density = torch.exp(-0.5 * ((torch.arange(SIZE) - SIZE / 2) / (SIZE / 6)) ** 2)
lines = torch.rand(SIZE, generator=torch.Generator().manual_seed(1)) < density / density.sum() * (
    SIZE / ACCELERATION
)
lines[SIZE // 2 - 4 : SIZE // 2 + 4] = True
pattern = lines.to(torch.complex64)[:, None].expand(SIZE, SIZE).contiguous()
A = linop.CartesianSense(sensitivities, (SIZE, SIZE), pattern=pattern)
NOISE = 0.02

print(f"{len(train_images)} slices of subject 0 to train on, {len(valid_images)} of subject 4")
print(f"{int(lines.sum())} of {SIZE} phase encodes")
24 slices of subject 0 to train on, 8 of subject 4
24 of 96 phase encodes
Dataset#
Each torchio subject holds one reference image as two real channels.
The augmentations are those that turn one MR image into another the scanner
could have produced: RandomGain applies
a random receiver gain and global phase (a complex scale within 20 per cent
in magnitude), and a flip and a small in-plane rotation vary the head’s
orientation. k-space is simulated from the augmented reference in the
collate function, so the measured data stay consistent with it. torchio’s
intensity transforms such as a gamma correction act on the real and
imaginary channels independently and would break that consistency.
A batch is a list of dictionaries, the form
Reconstruction takes: the data, the
operator, the reference, and the adjoint reconstruction the iteration starts
from.
augmentation = torchio.Compose(
    [
        learning.RandomGain(log_scale=0.2),
        torchio.RandomFlip(axes=(0,), flip_probability=0.5),
        torchio.RandomAffine(scales=0, degrees=(0, 0, 0, 0, -8, 8), translation=0),
    ]
)


def subjects(images):
    return [
        torchio.Subject(image=torchio.ScalarImage(tensor=learning.as_real(x)[..., None]))
        for x in images
    ]


def measured(x, generator=None):
    """One item: simulated k-space of ``x``, the operator, the reference and ``A^H y``."""
    y = A(x) + NOISE * torch.randn(A.oshape, dtype=torch.complex64, generator=generator)
    return {"y": y, "A": A, "target": x, "x0": A.H(y)}


def collate(batch):
    return [measured(learning.as_complex(s["image"][torchio.DATA][..., 0])) for s in batch]


train_loader = DataLoader(
    torchio.SubjectsDataset(subjects(train_images), transform=augmentation),
    batch_size=4,
    shuffle=True,
    collate_fn=collate,
)
generator = torch.Generator().manual_seed(2)
valid_items = [measured(x, generator) for x in valid_images]
valid_loader = DataLoader(valid_items, batch_size=4, collate_fn=list)
Network#
A two-dimensional UNet on the real and imaginary
planes, conditioned on the iteration index (steps=True);
ComplexNet lays the complex image out as those
planes and scales it to unit peak around the call. The network is residual
and starts as the identity, so the untrained stack is plain gradient
descent. ImplicitPrior with step=True passes
each iteration’s index to it.
network = learning.UNet(2, spatial=2, widths=(16, 32, 64), steps=True)
prior = priors.ImplicitPrior(learning.ComplexNet(network, spatial=2), step=True)
block = optim.ISTBlock(prior, step=1.0)
block.step.requires_grad_()

weights = sum(p.numel() for p in network.parameters())
print(f"{weights} weights, {2 * weights / 1e6:.2f} MB stored in half precision")
235730 weights, 0.47 MB stored in half precision
Stage 1: the denoiser alone#
The inputs are reconstructions of increasing quality – the zero-filled coil combination \(A^H y\), and CG-SENSE after 2, 5 and 20 iterations – each paired with the fully sampled reference and with the iteration index at which the unrolled network is expected to meet an image of that quality. The pairs are computed once; neither the unrolling nor the encoding enters this stage, which makes it the cheapest of the three.
STAGES = {0: 0, 2: 1, 5: 2, 20: 3}  # CG iterations -> iteration index

pairs = []
for x in train_images:
    item = measured(x)
    for iterations, index in STAGES.items():
        degraded = item["x0"] if 0 == iterations else optim.cg(item["y"], A, maxiter=iterations)
        pairs.append({"input": degraded, "target": x, "step": index})

trainer = lightning.Trainer(
    max_epochs=15,
    accelerator="cpu",
    logger=False,
    enable_checkpointing=False,
    enable_model_summary=False,
    enable_progress_bar=False,
)
stage = learning.Reconstruction(learning.ComplexNet(network, spatial=2), "denoiser", lr=2e-3)
trainer.fit(
    stage,
    DataLoader(pairs, batch_size=8, shuffle=True, collate_fn=list),
    DataLoader(pairs[:16], batch_size=8, collate_fn=list),
)
/opt/hostedtoolcache/Python/3.12.14/x64/lib/python3.12/site-packages/lightning/pytorch/utilities/_pytree.py:21: `isinstance(treespec, LeafSpec)` is deprecated, use `isinstance(treespec, TreeSpec) and treespec.is_leaf()` instead.
/opt/hostedtoolcache/Python/3.12.14/x64/lib/python3.12/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:434: The 'val_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=3` in the `DataLoader` to improve performance.
/opt/hostedtoolcache/Python/3.12.14/x64/lib/python3.12/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:434: The 'train_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=3` in the `DataLoader` to improve performance.
Stage 2: one iteration at a time#
detach=True starts every iteration from a detached state, and the greedy
stage back-propagates each iteration’s loss before the next iteration runs,
so memory holds one iteration. The losses are weighted geometrically along
the stack, the last ten times the first, since the last image is the one
delivered. The network now sees its own iterates, which the CG-SENSE images
of stage 1 only approximated.
psnr = PSNRMetric(max_val=1.0)
ssim = SSIMMetric(spatial_dims=2, data_range=1.0)


def quality(model):
    """Mean PSNR and SSIM of the magnitude over the validation slices."""
    with torch.no_grad():
        made = torch.stack([model(i["y"], A, i["x0"]) for i in valid_items]).abs()[:, None]
    truth = torch.stack(valid_images).abs()[:, None]
    return float(psnr(made, truth).mean()), float(ssim(made, truth).mean())


scores = {"untrained": None}
greedy = learning.Unrolled(block, iterations=ITERATIONS, detach=True)
scores["denoiser pretrained"] = quality(greedy)

trainer = lightning.Trainer(
    max_epochs=8,
    accelerator="cpu",
    logger=False,
    enable_checkpointing=False,
    enable_model_summary=False,
    enable_progress_bar=False,
)
trainer.fit(learning.Reconstruction(greedy, "greedy", lr=1e-3), train_loader, valid_loader)
scores["greedy"] = quality(greedy)
Stage 3: the whole stack#
The loss is now on the final image alone, so the earlier iterations are free
to produce whatever intermediate image serves the last one best.
checkpoint=True stores only the image between iterations and recomputes
each iteration’s activations during the backward pass: the gradient is the
exact end-to-end one, at the memory of those images plus one iteration.
stack = learning.Unrolled(block, iterations=ITERATIONS, checkpoint=True)
trainer = lightning.Trainer(
    max_epochs=4,
    accelerator="cpu",
    logger=False,
    enable_checkpointing=False,
    enable_model_summary=False,
    enable_progress_bar=False,
)
trainer.fit(learning.Reconstruction(stack, "end-to-end", lr=3e-4), train_loader, valid_loader)
scores["end to end"] = quality(stack)
Results#
The untrained stack is four gradient steps from \(A^H y\), since the residual network starts as the identity. CG-SENSE with twenty iterations is the baseline without a learned prior. Scores are the mean PSNR and SSIM of the magnitude over the eight validation slices of subject 4.
untrained = learning.Unrolled(
    optim.ISTBlock(priors.ImplicitPrior(lambda v: v), step=1.0), iterations=ITERATIONS
)
scores["untrained"] = quality(untrained)
cg = torch.stack([optim.cg(i["y"], A, maxiter=20) for i in valid_items])
truth = torch.stack(valid_images)
scores["CG SENSE, 20 iterations"] = (
    float(psnr(cg.abs()[:, None], truth.abs()[:, None]).mean()),
    float(ssim(cg.abs()[:, None], truth.abs()[:, None]).mean()),
)
for name, (p, s) in scores.items():
    print(f"{name:>24}   PSNR {p:5.2f} dB   SSIM {s:.3f}")
print(f"learned step: {float(block.step.detach()):.3f}")
               untrained   PSNR 26.45 dB   SSIM 0.654
     denoiser pretrained   PSNR 27.34 dB   SSIM 0.928
                  greedy   PSNR 27.72 dB   SSIM 0.737
              end to end   PSNR 28.93 dB   SSIM 0.812
 CG SENSE, 20 iterations   PSNR 24.30 dB   SSIM 0.558
learned step: 1.153
Each stage starts from the weights the previous one left, and each raises the PSNR. The pretrained denoiser scores a high SSIM but a low PSNR: inside the iteration it meets its own iterates rather than the CG-SENSE images it was trained on, and the greedy stage adapts it to them. With one training subject and a few epochs per stage, the numbers show the ordering of the stages, not what each reaches on a real dataset.
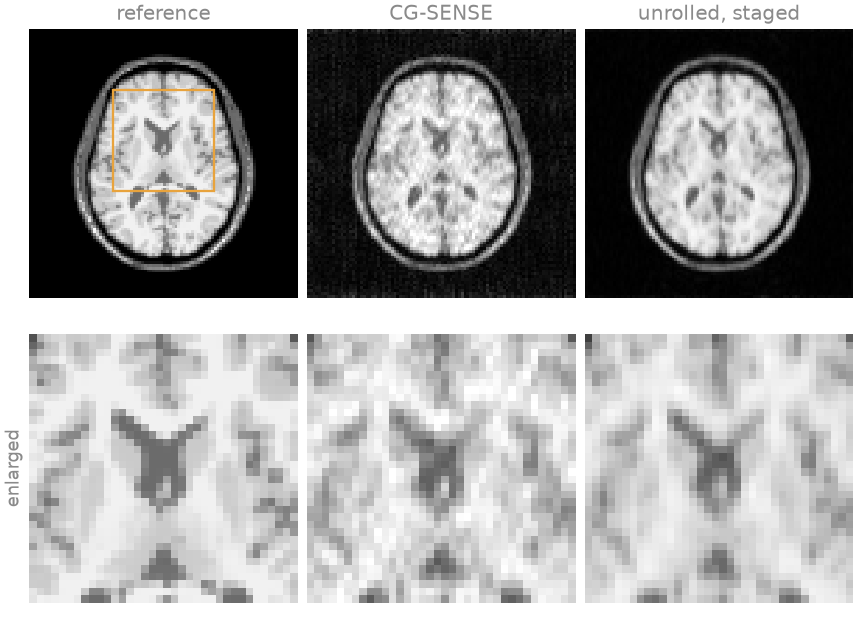
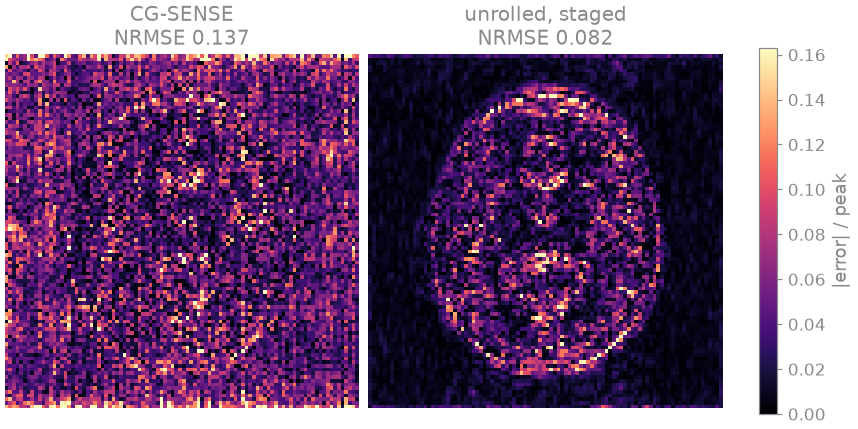
In the images below, CG-SENSE at \(R = 4\) keeps a grainy, spatially varying noise – the g-factor amplification of the coil unfolding – and faint aliasing along the phase-encode direction (vertical). The unrolled network removes both; its error concentrates at tissue boundaries, where it slightly smooths the cortex.
Storing the weights#
The weights are stored in half precision, which halves the file and loses
nothing a float16 or bfloat16 inference would keep. load_state_dict
casts them back to the network’s precision.
compact = {name: value.half() for name, value in stack.state_dict().items()}
restored = learning.Unrolled(
    optim.ISTBlock(
        priors.ImplicitPrior(
            learning.ComplexNet(
                learning.UNet(2, spatial=2, widths=(16, 32, 64), steps=True), spatial=2
            ),
            step=True,
        )
    ),
    iterations=ITERATIONS,
)
restored.load_state_dict(compact)
print(f"restored: PSNR {quality(restored)[0]:5.2f} dB")
restored: PSNR 28.94 dB
References#
Total running time of the script: (1 minutes 35.137 seconds)