nlop.IRGNM#
- class bartorch.nlop.IRGNM#
Bases:
Iteratively regularized Gauss-Newton for
F(x) = y, loopingIRGNMBlock.Each step linearizes at the current point and solves
min_u ||DF u - r||^2 + alpha ||u||^2 + R(u)where
ris the residual carried to the linearization; the weight is then divided byredu, down toalpha_min.Ris whatever the inner solver regularizes with, and is nothing at all for conjugate gradients.- Parameters:
iterations (int, default=8) – Gauss-Newton steps.
alpha (float, default=1.0) – Initial Tikhonov weight.
alpha_min (float, default=0.0) – What the weight decays towards.
alpha_min0 (float, default=0.0) – A floor the decayed weight is never taken below. Only the second form has it; BART’s
irgnmdoes not.redu (float, default=2.0) – Factor the weight is divided by after each step.
cg_maxiter (int, default=30) – Conjugate-gradient iterations per step, for the built-in solver.
cg_tol (float, default=0.0) – Conjugate-gradient tolerance per step, for the built-in solver.
inner (solver or None, default=None) – A configured solver from
bartorch.optimfor the linearized problem, whose regularizers become theRabove.Noneruns BART’s first form, with the inverse inside the library, asnlinvdoes.fuse (bool, default=True) – Lower a coil composition so that its encoding is applied once as its normal operator.
Examples
Plain, which is
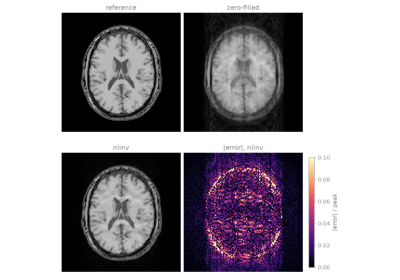
nlinv:>>> nlop.IRGNM(iterations=8)(kspace, F, x0=start)
The same method with the linearized problem written out here, which is
iter4_irgnm2to the bit:>>> nlop.IRGNM(iterations=8, inner=optim.CG())(kspace, F, x0=start)
Wavelet-regularized:
>>> nlop.IRGNM(inner=optim.FISTA(priors.Wavelet((-1, -2), 0.001), maxiter=30))(
...     kspace, F, x0=start
... )
Several terms at once, which is ADMM’s job:
>>> nlop.IRGNM(
...     inner=optim.ADMM(
...         [priors.Wavelet((-1, -2), 0.001), priors.TotalVariation((-1, -2), 0.01)]
...     )
... )(kspace, F, x0=start)
Notes
The two forms are the same method and not the same arithmetic. The first carries
alpha (xref - x)into the right-hand side and solves for a step; the second shifts byxref, carries an extraDF (x - xref)into the residual, and solves for the iterate itself. They agree in exact arithmetic and differ in the last bits, so a run withinner=will not reproduce one without it. Each reproduces BART’s own loop of its form –iter4_irgnmand, withinner=optim.CG(),iter4_irgnm2– and the suite holds both to that.- __call__()#
Fit
F(x) = y.- Parameters:
y (torch.Tensor) – Data of
F.oshape, with an optional batch axis in front.F (NonlinearOperator or LinearOperator) – The forward model, with a bundle; a linear one is converted with
to_nonlinear().x0 (torch.Tensor or tuple of torch.Tensor, default=None) – Starting point; see
IRGNMBlock.start().xref (torch.Tensor or tuple of torch.Tensor, default=None) – Regularization centre. Without one the steps are regularized towards zero, as BART does.
- Returns:
Complex64 solution, one tensor per input of
F.- Return type:
torch.Tensor or tuple of torch.Tensor