

Note
Go to the end to download the full example code.
Noise prewhitening#

In this tour you measure how much signal-to-noise ratio (SNR) a SENSE reconstruction loses when the noise of the receive channels is correlated, and how much of it you get back by prewhitening with a noise-only acquisition.
The thermal noise of a receive array is correlated between channels, through mutual inductance between the coil elements and noise sources shared in the sample, and its level differs from channel to channel, with the elements’ size, loading and preamplifier gain. Least squares is the maximum-likelihood estimate only when the noise is white, that is when the channel noise covariance \(\Psi\) is proportional to the identity. A reconstruction that ignores \(\Psi\) weights every channel equally, and does not combine them with the best SNR [1]. Prewhitening multiplies the data by a matrix \(W\) with \(W \Psi W^H = I\), which makes the channel noise white; you then calibrate the sensitivities on the whitened channels and run SENSE on them unchanged [2]. You estimate \(\Psi\) from a noise scan, an acquisition with the RF transmitter off that most vendors run before every protocol.
You measure the SNR by the pseudo-replica method [3]: repeat the same reconstruction on independent noise realisations added to one noise-free acquisition, and take the standard deviation across the repetitions as the noise of each voxel. That is how you get SNR and g-factor maps for an iterative reconstruction, for which there is no closed form of the noise propagation.
Prerequisites: lessons 2 and 3, 2. From k-space to an image and 3. Coil sensitivities.
Learning objectives
Estimate the channel noise covariance from a noise scan and whiten the data with
bartorch.tools.whiten().Measure an SNR map by the pseudo-replica method.
Quantify the SNR gain that prewhitening gives a SENSE reconstruction.
Correlated channel noise#
Your object is the BrainWeb slice of lesson 2, seen by BART’s analytical eight-channel head coil; how it is built is hidden on this page. The noise of your simulated array couples the channels by a correlation coefficient that falls as \(0.5^{|i-j|}\) with the distance between their indices, and the channels’ noise standard deviations range from 0.6 to 1.6 times a common level.
import torch

import bartorch
import bartorch.tools as bt

from bartorch import apps

COILS = 8
SIGMA = 0.01  # noise level, relative to the image's peak

sensitivities = bt.coils(t=bt.grid(D=(SIZE, SIZE, 1)), n=COILS)[:, 0]
sensitivities /= bartorch.rss(sensitivities, axes=(0,), keepdim=True)

channels = torch.arange(COILS)
levels = torch.linspace(0.6, 1.6, COILS)
correlation = 0.5 ** (channels[:, None] - channels[None, :]).abs().float()
covariance = levels[:, None] * correlation * levels[None, :]
The noise scan records the same channels with no signal.
bartorch.tools.whiten() takes the data and the noise scan, estimates
\(\Psi\) as the sample covariance of the noise scan, and whitens the
data with it. Applied to the noise scan itself, it returns white noise:
noise_scan = channel_noise((SIZE, SIZE))[:, None]  # (coils, 1, y, x)
whitened_scan = bt.whiten(noise_scan, noise_scan)
off-diagonal covariance: 0.202 measured
                         0.000 after whitening
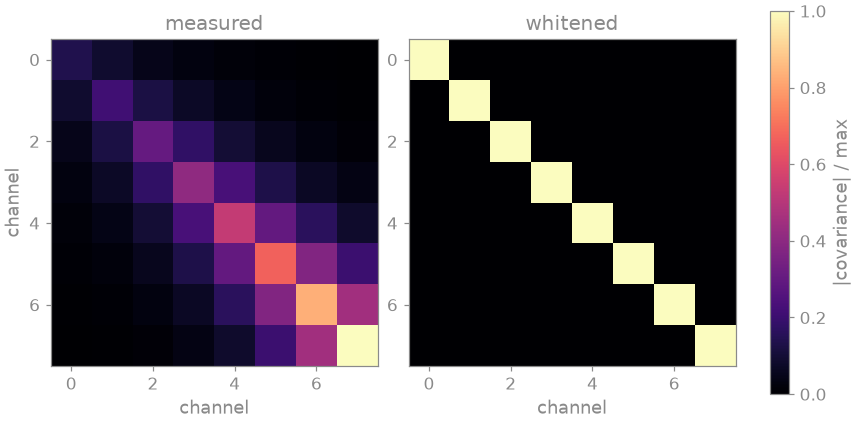
The printed number is the mean magnitude of the off-diagonal covariance entries relative to the mean diagonal entry, which is zero for uncorrelated channels. In the figure, the measured covariance has a strong diagonal whose entries grow with the channel index, the unequal noise levels, and off-diagonal bands, the correlation. After whitening it is the identity.
Acquisition and calibration#
You acquire every second phase encode (\(R = 2\)), with 24 central lines kept as the ACS region. Each pseudo-replica adds a new noise realisation to the same noise-free k-space. You calibrate the sensitivities once per pipeline, from the first replica: from the channels as measured, and from the whitened channels.
CALIBRATION = 24
REPLICAS = 32

lines = torch.zeros(SIZE)
lines[::2] = 1.0
centre = slice(SIZE // 2 - CALIBRATION // 2, SIZE // 2 + CALIBRATION // 2)
lines[centre] = 1.0
pattern = lines.reshape(SIZE, 1).to(torch.complex64)

noiseless = bartorch.fft(sensitivities * image, axes=(-2, -1), unitary=True)


def acquire():
    """One replica: the noise-free k-space plus new noise, sampled."""
    noisy = noiseless + channel_noise((SIZE, SIZE))
    return (noisy * pattern)[:, None]


first = acquire()
maps_measured = bt.ecalib(first, maps=1, calib_size=CALIBRATION, crop=0.8)
maps_whitened = bt.ecalib(
    bt.whiten(first, noise_scan),
    maps=1,
    calib_size=CALIBRATION,
    crop=0.8,
)
Pseudo-replicas#
Both pipelines run the same reconstruction, conjugate-gradient SENSE with a small Tikhonov weight and a fixed number of iterations. The only difference is whether you whiten the data first.
plain, prewhitened = [], []
for _ in range(REPLICAS):
    data = acquire()
    plain.append(apps.pics(data, maps_measured, l2=1e-3, maxiter=30))
    data = bt.whiten(data, noise_scan)
    prewhitened.append(apps.pics(data, maps_whitened, l2=1e-3, maxiter=30))

plain, prewhitened = torch.stack(plain), torch.stack(prewhitened)
The SNR of a voxel is the magnitude of the mean reconstruction over the standard deviation across replicas. You report both pipelines over the white matter, where the phantom is homogeneous.
def snr_map(replicas):
    return replicas.mean(0).abs() / replicas.std(0)


gain = snr_map(prewhitened) / snr_map(plain)
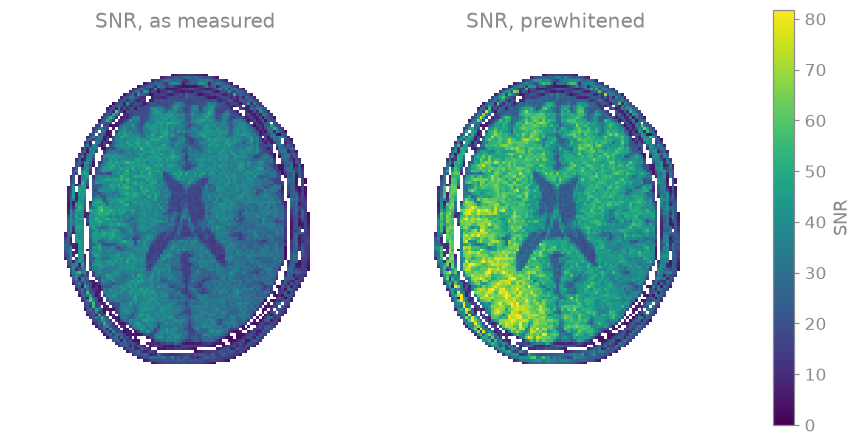
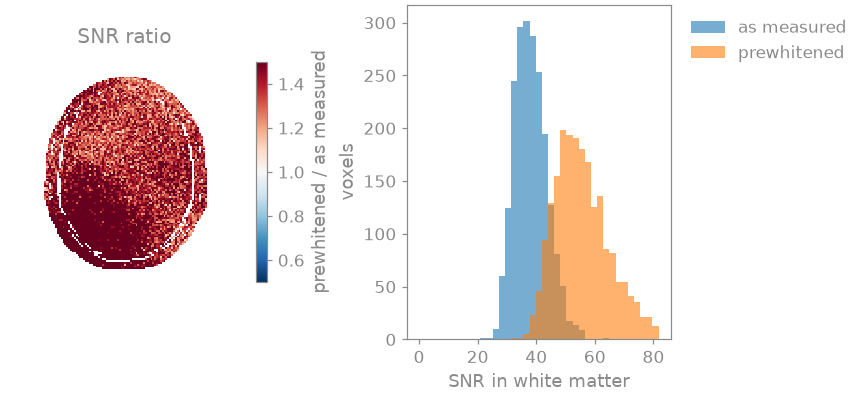
 as measured  white-matter SNR   38.1 (median 37.7)
 prewhitened  white-matter SNR   55.8 (median 54.5)
SNR ratio, prewhitened over as measured: 1.43 (median)
Prewhitening raises the SNR throughout the head, and the white-matter histogram shifts by the ratio printed above. The gain varies in space: it is largest in the posterior half of the head (the bottom of the image). Both the quietest channels, 0 and 1, and the noisiest, 6 and 7, are most sensitive there. Without whitening, the least-squares fit gives them all the same weight; after whitening, each channel enters with the weight its noise level warrants, and that matters most where channels of very different noise levels overlap. How large the gain is depends on the array’s noise correlation and on the spread of its channel noise levels, and what you measured here is for one simulated covariance. With uncorrelated channels of equal noise level it is one.
As a spec#
What this tour built, stated the way you would ask an agent for it:
Measure the SNR gain of noise prewhitening for a Cartesian SENSE
reconstruction with bartorch. Simulate an 8-channel acquisition with a
known channel noise covariance and a noise-only scan; undersample by 2
along y with a 24-line ACS block. Calibrate one set of ESPIRiT maps
(bt.ecalib, crop 0.8) from the data as measured and from the data
whitened by bt.whiten(data, noise_scan). Reconstruct 32 pseudo-replicas
with apps.pics (l2=1e-3, 30 iterations) in both pipelines, and report
the SNR map (|mean| / std across replicas), its white-matter mean and
median, and the median prewhitened / as-measured SNR ratio.
References#
Total running time of the script: (0 minutes 4.922 seconds)