

Note
Go to the end to download the full example code.
5. Choosing a regularizer#

In lesson 2 you reconstructed an undersampled scan with a wavelet penalty at a weight of 0.004, both fixed without justification. In this lesson you choose them. You reconstruct one noisy, undersampled SENSE acquisition with three different penalties, sweep the weight of each, and compare under- and over-regularized images. Then you combine two penalties in one reconstruction.
The mental model: at high acceleration or low SNR, the SENSE problem is ill-conditioned: the data do not determine the image uniquely, and a plain least-squares fit amplifies the noise by the g-factor. You therefore add prior knowledge about the image as a penalty,
where \(A\) is the SENSE encoding, \(g\) a convex function, \(G\) a linear transform and \(\lambda\) the regularization weight. Tikhonov regularization favours a small image; a wavelet \(\ell_1\) penalty favours an image that is sparse in a wavelet basis, as in compressed sensing; total variation (TV) favours one that is piecewise constant. The weight sets the balance between data consistency and the penalty. Regularizers introduces the penalties and Solvers the algorithms.
Learning objectives
Pass regularization terms from
bartorch.priorstobartorch.apps.pics(), with a solver the term admits.Compare Tikhonov, wavelet \(\ell_1\) and TV regularization on the same data, by their images and error maps.
Choose a regularization weight by the error against a reference, and recognise under- and over-regularization in the image.
Combine two terms in one reconstruction.
Previous: 4. Joint reconstruction of image and sensitivity maps. Next:
6. Custom encoding and solver, where you build the operator, the term and
the solver that pics puts together, and run them yourself.
Simulated acquisition#
The object, the coils and the sampling are those of lesson 2: the BrainWeb slice [1], eight channels, and one phase-encoding line in three around a fully sampled ACS block of 24 lines. The one change is the noise, three times stronger: complex Gaussian noise of variance \(3 \times 10^{-4}\) per sample of the unitary transform of an image whose peak is one. At this level the noise amplified by the inversion, and not only the aliasing, sets the error of an unregularized reconstruction.
import torch

import bartorch
import bartorch.tools as bt

from bartorch import apps, priors

ACCELERATION = 3
CALIBRATION = 24

clean = bartorch.fft(sensitivities * image, axes=(-2, -1), unitary=True)
kspace = bt.noise(clean, n=3e-4, s=42)
measured = kspace[:, None] * simulate(ACCELERATION, CALIBRATION)

maps = bt.ecalib(measured, maps=1, calib_size=CALIBRATION, crop=0.8)
Tikhonov, wavelet and TV penalties#
Each penalty admits particular solvers; pics takes the term and the
solver:
Tikhonov, \(g(x) = \tfrac12\|x\|_2^2\), is the
l2argument. It keeps the problem quadratic, so conjugate gradients solve it.The wavelet term \(\|\Psi x\|_1\) [2] is
bartorch.priors.Wavelet. Its transform is orthogonal and sits inside its proximal operator, so FISTA [3] solves it.Total variation, \(\sum_r \|(\nabla x)_r\|_2\) [4], is
bartorch.priors.TotalVariation. The finite differences \(\nabla\) have no such closed-form proximal operator, so TV needs a splitting method, here ADMM [5].
The first argument of a term is the tensor axes it acts along, here the two image axes. You run each penalty over four weights:
sweeps = {
    "Tikhonov": [0.01, 0.03, 0.1, 0.3],
    "wavelet": [0.003, 0.006, 0.012, 0.03],
    "total variation": [0.002, 0.006, 0.012, 0.04],
}


def reconstruct(name, weight, data=measured):
    if name == "Tikhonov":
        return apps.pics(data, maps, l2=weight, maxiter=100)
    if name == "wavelet":
        term, solver = priors.Wavelet((-1, -2), weight), "fista"
    else:
        term, solver = priors.TotalVariation((-1, -2), weight), "admm"
    return apps.pics(data, maps, regularizers=term, solver=solver, maxiter=100)


def nrmse(estimate):
    return bt.nrmse(image.abs(), estimate.abs(), scaled=True)


results = {
    name: {weight: reconstruct(name, weight) for weight in weights}
    for name, weights in sweeps.items()
}
scores = {}
for name, sweep in results.items():
    scores[name] = {weight: nrmse(x) for weight, x in sweep.items()}
best = {name: min(sweep, key=sweep.get) for name, sweep in scores.items()}
for name, weight in best.items():
    print(f"{name:>16}: best weight {weight}, NRMSE {scores[name][weight]:.3f}")
       Tikhonov: best weight 0.03, NRMSE 0.082
        wavelet: best weight 0.006, NRMSE 0.056
total variation: best weight 0.006, NRMSE 0.059
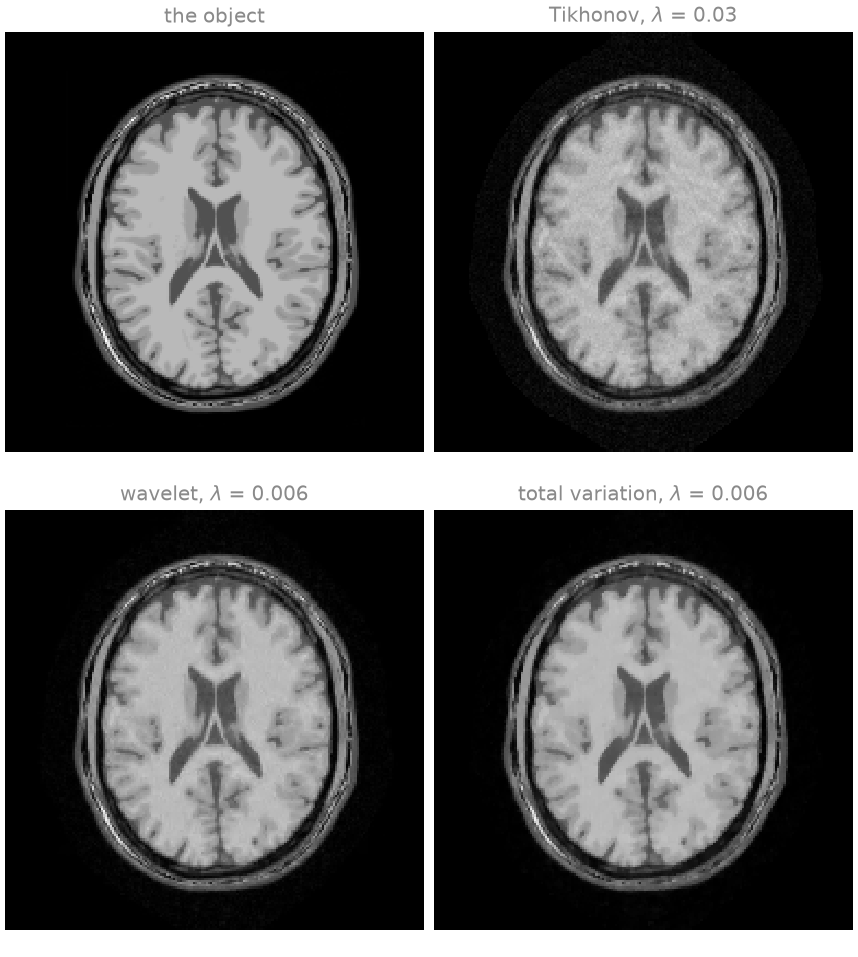
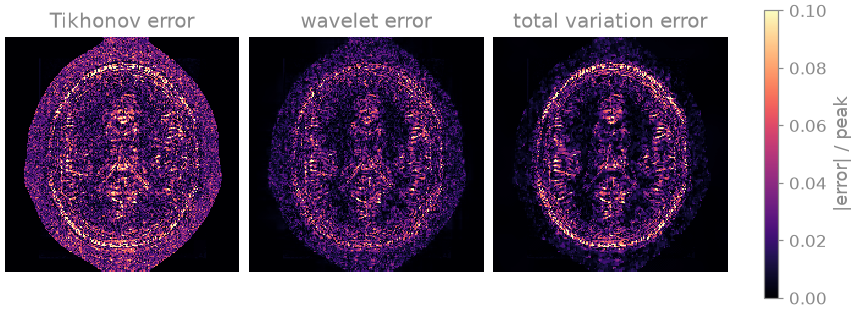
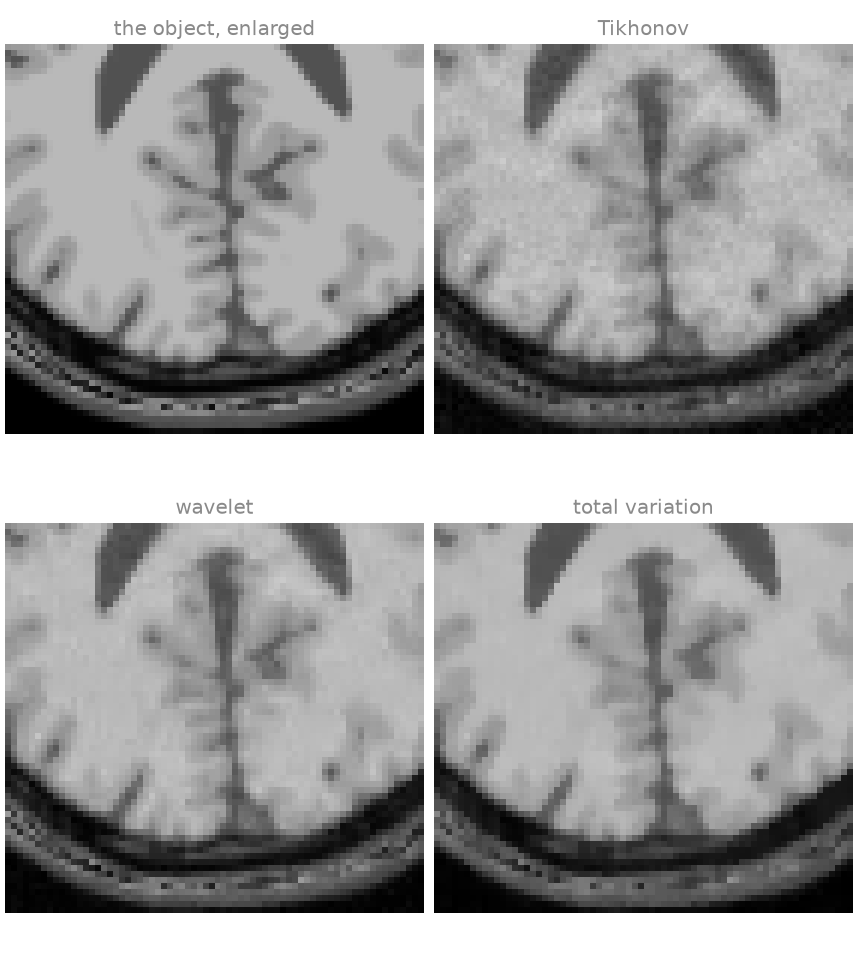
You see each penalty at its best weight, then the error maps on one scale, then the occipital cortex enlarged. Tikhonov leaves the amplified noise and the incoherent aliasing of the random sampling across the whole head: a quadratic penalty strong enough to remove them would blur the image too, so its best weight leaves them in. The two sparsity penalties remove most of the noise and keep the tissue boundaries, which is the much darker error inside the brain. Their residual artefacts differ in the enlarged region: the wavelet penalty leaves a blotchy texture in white matter, and TV turns the gradual intensity changes within white matter into patches of constant intensity (staircasing).
The regularization weight#
Too small a weight leaves the noise in; too large a weight takes image detail out with it. The error against the truth has a minimum in between, and the sweep above spans a factor of ten or more for each penalty to find it. You can do that here because you know the truth; for measured data you choose the weight by a criterion that needs no reference, or fix it once for a protocol.
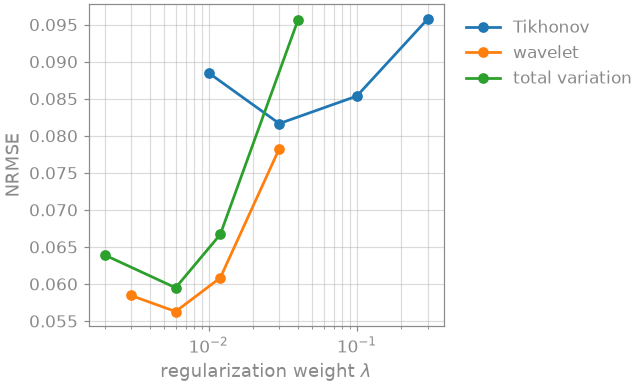
Each curve has its minimum inside the sweep. You cannot compare weights across penalties, because the functions differ; only where each minimum lies means something. At its minimum, each sparsity penalty reaches a lower error than Tikhonov at its own, for this image and this noise level.
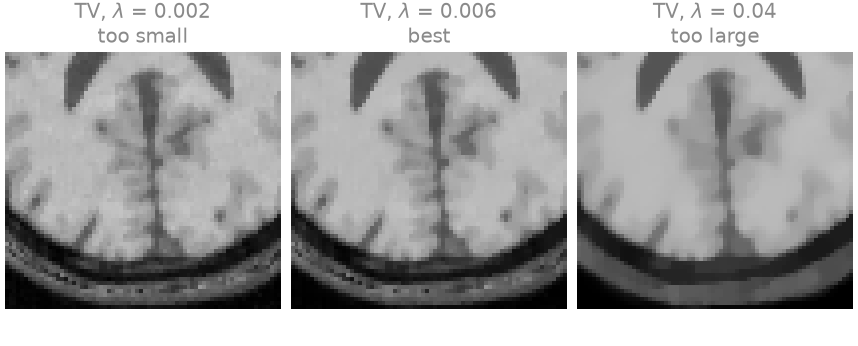
The three TV images show both failure modes. At the smallest weight the noise and the aliasing remain. At the largest, the cortex is flattened into patches of constant intensity and thin gyri merge.
Combined penalties#
regularizers also takes a list, and the terms are added. ADMM splits
the variable once per term with a transform of its own, so it takes any
combination; FISTA takes only terms whose transform is the identity. Here
is wavelet plus TV, each at half its best weight:
combined = apps.pics(
    measured,
    maps,
    regularizers=[
        priors.Wavelet((-1, -2), best["wavelet"] / 2),
        priors.TotalVariation((-1, -2), best["total variation"] / 2),
    ],
    solver="admm",
    maxiter=100,
)
print(f"wavelet + TV: NRMSE {nrmse(combined):.3f}")
wavelet + TV: NRMSE 0.058
The sum reaches an error comparable to either penalty alone. Whether a combination beats its parts depends on the image and the weights, and you find out with a comparison like the one above rather than by assuming it.
nrmse(..., scaled=True) fits one global factor before comparing, so it
compares the shape of the image and not its overall scale.
Exercise: noise level and weight#
Does the best weight depend on the noise? Sweep the wavelet weights again on the same scan with a third of the noise and with three times as much:
levels = {1e-4: {}, 3e-4: scores["wavelet"], 1e-3: {}}
for level, sweep in levels.items():
    if sweep:
        continue
    noisy = bt.noise(clean, n=level, s=42)
    data = noisy[:, None] * simulate(ACCELERATION, CALIBRATION)
    for weight in sweeps["wavelet"]:
        sweep[weight] = nrmse(reconstruct("wavelet", weight, data))
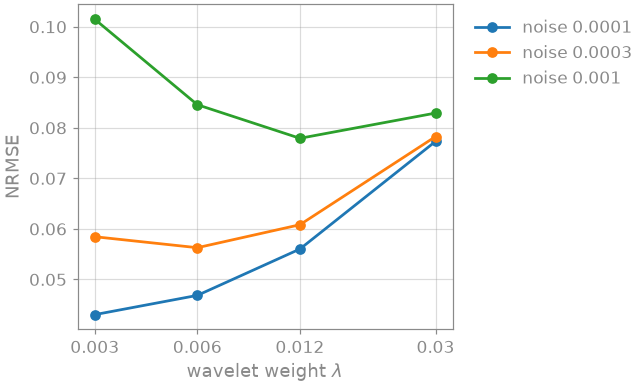
noise 0.0001: best wavelet weight 0.003
noise 0.0003: best wavelet weight 0.006
noise 0.001: best wavelet weight 0.012
The best weight moves with the noise: in this sweep it is 0.003 at a third of the noise, 0.006 at the level used above, and 0.012 at three times the noise, and the error at every weight rises with the noise. At the lowest noise the minimum lies at the smallest weight of the sweep, so the best weight there may be smaller still; extend the sweep downwards to find it. A weight chosen for one SNR is therefore not the best for another.
As a spec#
What this lesson built, stated the way you would ask an agent for it:
With bartorch, reconstruct a 2D Cartesian 8-channel k-space, undersampled
3-fold along y around a 24-line ACS block, with ESPIRiT maps (bt.ecalib,
crop 0.8) and apps.pics, 100 iterations each: Tikhonov (l2) at
0.01-0.3 with CG, priors.Wavelet over the last two axes at 0.003-0.03
with FISTA, and priors.TotalVariation at 0.002-0.04 with ADMM. Pick each
weight by the lowest NRMSE against the reference (scaled=True), show the
images and error maps at the best weights, and run wavelet + TV at half
of each best weight with ADMM.
References#
Total running time of the script: (0 minutes 17.981 seconds)