

Note
Go to the end to download the full example code.
9. Nonlinear inversion for T2 mapping#

In lesson 8 you reconstructed one image from undersampled radial data, and in lesson 4 you solved a model that is nonlinear in its unknowns, image times coil sensitivities, by Gauss-Newton. In this lesson you apply both to quantitative imaging. You estimate a \(T_2\) map from an undersampled multi-echo spin-echo scan twice: first by reconstructing an image per echo and fitting the decay voxel by voxel, then by fitting the signal model directly to the k-space data, and you compare the accuracy of the two at the same undersampling.
In a multi-echo spin-echo (CPMG) scan the signal of each voxel decays from echo to echo as \(M_0 \exp(-\mathrm{TE}/T_2)\). With each echo undersampled, each echo image is a separate ill-posed reconstruction with its own aliasing and noise, and a voxelwise fit cannot distinguish those from decay. Model-based reconstruction [1] [2] puts the signal model inside the forward operator,
where \(P_e\) is the sampling pattern of echo \(e\), \(F\) the Fourier transform, \(S_c\) the sensitivity of coil \(c\), \(M\) the signal model and \(\theta\) the parameter maps. You then solve for \(\theta\) from the k-space of all echoes at once. The unknowns are three real maps rather than eight complex images, and every echo constrains all of them. The operator is nonlinear in \(\theta\), so you solve it with the iteratively regularized Gauss-Newton method (IRGNM) of lesson 4, over a different model.
Learning objectives
Write a \(T_2\) decay as a signal model,
bartorch.nlop.MultiEcho, a BlochSim simulator wrapped as a BART nonlinear operator.Fit it to reconstructed echo images with
bartorch.apps.mobafit(), and directly to k-space by composing it with the encoding and solving withbartorch.nlop.IRGNM.Run the k-space fit in one call with
bartorch.apps.moba().Explain, from the echo images and the error maps, why the model-based fit is more accurate at the same undersampling.
Previous: 8. Radial SENSE. Next: 10. Plug-and-play reconstruction, where you replace a penalty you wrote down with a learned denoiser. The Tours Subspace-constrained T1 mapping and Parameter maps from scanner images apply a linear subspace model and the same signal model to DICOM images.
Multi-echo phantom#
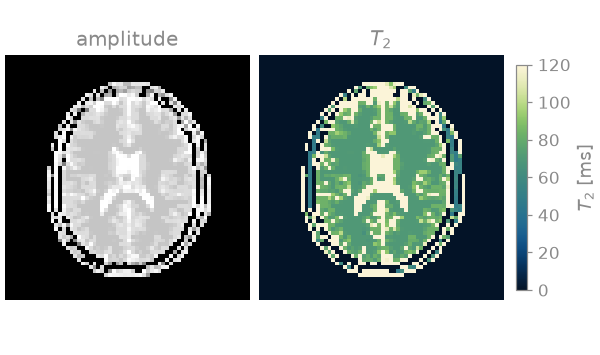
The object is the BrainWeb slice of lesson 2 on a 64 matrix, described by two maps: a proton-density amplitude and a \(T_2\) per voxel, each combined from the tissue classes in the voxel by membership. Eight spin echoes are acquired 12.5 ms apart. The echo images follow the mono-exponential decay, written out explicitly here rather than taken from the model that is fitted below.
import time

import torch

import bartorch.tools as bt

from bartorch import apps, linop, nlop, optim

ECHOES = 8
ECHO_TIMES = torch.tensor([12.5 * (echo + 1) for echo in range(ECHOES)])  # ms

decay = torch.exp(-ECHO_TIMES[:, None, None] / t2[None])
contrasts = (amplitude[None] * decay).to(torch.complex64)
print(f"echo images {tuple(contrasts.shape)}: (echo, y, x)")
echo images (8, 64, 64): (echo, y, x)
These are the maps to be estimated. In the BrainWeb table white matter has a \(T_2\) of 70 ms and grey matter 83 ms; the cerebrospinal fluid in the ventricles, at 329 ms, saturates the window, which is chosen to spread white and grey matter over the colour scale [3].
Echo undersampling#
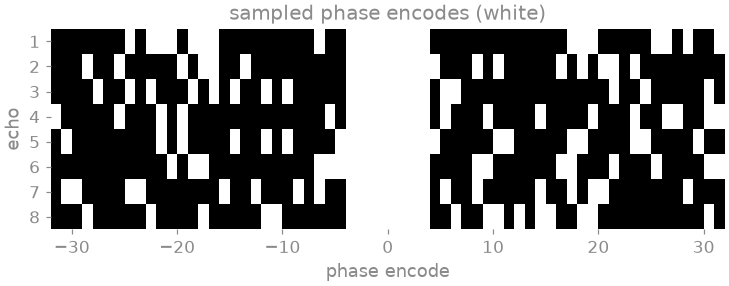
Each echo is sampled at a quarter of the phase encodes (\(R = 4\)): eight fully sampled central lines and the rest drawn at random, with a different draw per echo, so that the missing lines differ between echoes. The echoes are a batch of the encoding rather than an axis inside it: they share the coils and the transform and differ only in the pattern. So the encoding \(E\) is the Cartesian SENSE operator of lesson 6 followed by a diagonal that applies each echo’s pattern to its samples.
ACCELERATION = 4


encoding = linop.CartesianSense(
    sensitivities,
    (ECHOES, SIZE, SIZE),
    ndim=2,
)
pattern = linop.Diagonal(lines.to(torch.complex64), encoding.oshape)
E = pattern @ encoding

measured = bt.noise(E(contrasts), n=1e-6, s=9)
data = measured / float(E.H(measured).abs().max())

print(f"{E.ishape} -> {E.oshape}")
(8, 64, 64) -> (8, 8, 64, 64)
Each row is one echo, each white column an acquired phase encode. The central block is common to all echoes; outside it, each echo has its own lines, so the aliasing differs from echo to echo.
The signal model#
bartorch.nlop.MultiEcho is the decay as a nonlinear operator: it
maps parameter maps to one image per echo. Its unknowns are \(T_2\) and
a complex amplitude, carried as three real maps in a bounded
parameterisation rather than in their own units. So you build a starting
point from values in physical units with
initial(), and convert a fit back to
milliseconds with split().
unknowns ('T2', 'amplitude.real', 'amplitude.imag'): (3, 64, 64) -> (8, 64, 64)
Two-step fit#
The conventional route has two steps. Reconstruct every echo by conjugate
gradients on the SENSE normal equations, then fit the model to the echo
images voxel by voxel with bartorch.apps.mobafit(), Levenberg-Marquardt
over the model alone.
STEPS = 20

start_time = time.perf_counter()
images = optim.CG(maxiter=40)(data, E)
two_step = apps.mobafit(images, M, iterations=STEPS, T2=80.0)
print(f"reconstruct, then fit: {time.perf_counter() - start_time:5.1f} s")
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/torch/jit/_script.py:1491: FutureWarning: `torch.jit.script` is deprecated. Please switch to `torch.compile` or `torch.export`.
  warnings.warn(
reconstruct, then fit:   0.7 s
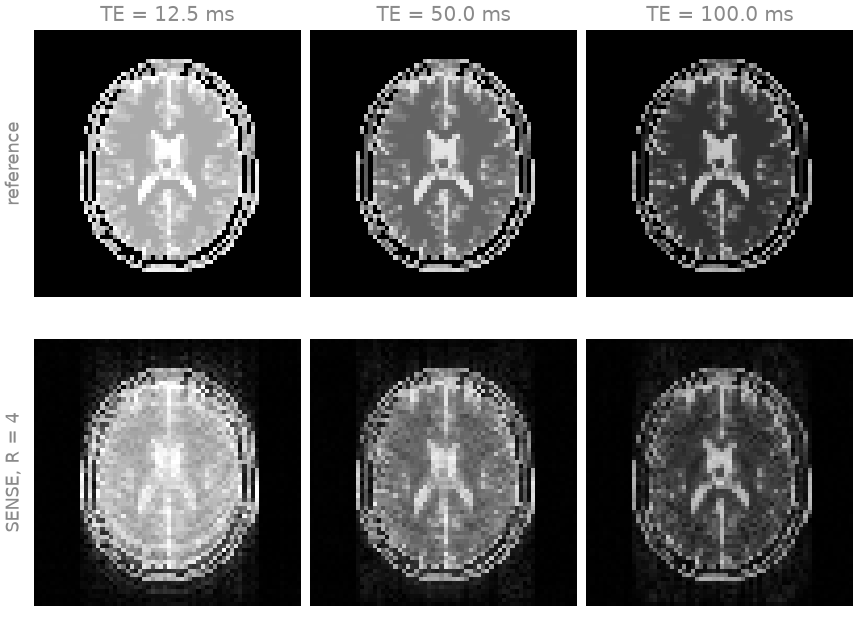
These images are the input of the voxelwise fit. Each reconstructed echo carries residual aliasing and noise, different in every echo because every echo has its own pattern. At the later echoes the signal has decayed and the relative error grows, so the late echoes, which determine \(T_2\) most, are also the least accurate.
Model-based forward operator#
The model-based route composes the model with the encoding, E @ M, and
fits the k-space directly with bartorch.nlop.IRGNM, the
Gauss-Newton solver of lesson 4. The derivative of the composition is the
encoding applied to the derivative of the model, which is the derivative a
Gauss-Newton step requires.
start_time = time.perf_counter()
solver = nlop.IRGNM(iterations=STEPS, cg_maxiter=100, cg_tol=0.1)
model_based = solver(data, E @ M, x0=start)
print(f"model inside the operator: {time.perf_counter() - start_time:5.1f} s")
model inside the operator: 17.0 s
Both routes are Gauss-Newton loops of the same number of steps. They differ
in the forward operator that maps the unknowns to the data: the model alone,
against echo images, or the model followed by the encoding, against k-space.
Without the encoding each voxel is a problem of its own, so mobafit
solves each step per voxel and damps each voxel separately.
Model-based reconstruction app#
bartorch.apps.moba() assembles the model-based fit from the
k-space, the model, the sensitivities and the sampling pattern, and returns
the maps in their own units. It scales the data by the rule of
bartorch.optim.data_scaling() and regularizes each Gauss-Newton step
towards the starting maps rather than towards zero, so its result is not
identical to the fit above.
apps.moba: 16.4 s
Map comparison#
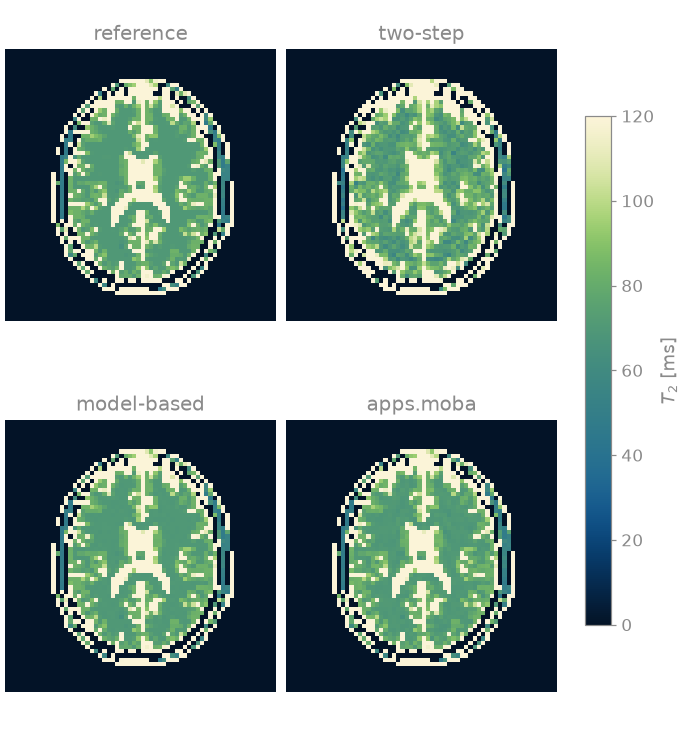
Read the three \(T_2\) maps back and compare them with the phantom, inside the head:
estimates = {
    "two-step": two_step["T2"],
    "model-based": M.split(model_based)["T2"],
    "apps.moba": one_call["T2"],
}

truth = t2[support]
for name, estimate in estimates.items():
    error = float((estimate[support] - truth).norm() / truth.norm())
    median = float(estimate[support].median())
    print(f"{name:>12}: median {median:5.1f} ms, relative error {error:.3f}")
print(f"{'phantom':>12}: median {float(truth.median()):5.1f} ms")
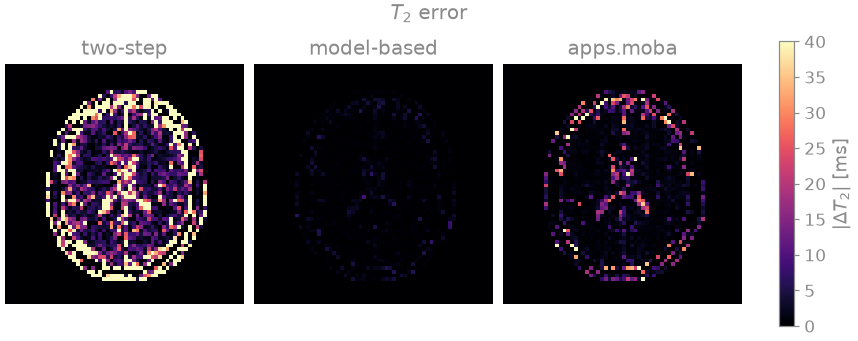
   two-step: median  86.2 ms, relative error 0.744
model-based: median  81.5 ms, relative error 0.007
  apps.moba: median  81.3 ms, relative error 0.057
    phantom: median  81.5 ms
The two-step map is dominated by the errors of the echo images: a voxelwise fit cannot distinguish residual aliasing from decay, and where a late echo is too bright or too dark the fitted \(T_2\) is far off. Its median is close to the phantom’s, but its relative error is the largest of the three. The model-based fits reach a much lower error from the same data, because the model admits only echo images that decay exponentially, and the aliasing of eight different sampling patterns is not such an image.
The fit inside the operator reproduces the phantom almost exactly, because
every voxel of the phantom decays with a single \(T_2\), as the model
assumes. A measured voxel holding two tissues decays with two, and a single
exponential cannot represent it. bartorch.apps.moba() regularizes
each Gauss-Newton step towards the starting maps, and its residual error is
largest where \(T_2\) is farthest from the starting value of 80 ms: in
the cerebrospinal fluid of the ventricles and at the scalp.
Because the maps are the solver’s unknowns, a regularizer passed to the
linearized problem, the inner solver of bartorch.apps.moba(),
penalizes the maps rather than the echo images. Without sensitivities,
bartorch.apps.moba() estimates the coils jointly with the maps, as
lesson 4 estimates them jointly with an image.
Model-based reconstruction describes the model-based approach in
more detail.
Exercise: fully sampled echoes#
Is the error of the two-step route caused by the voxelwise fit or by the echo images it is given? Run the same fit on the fully sampled, noise-free echo images of the phantom:
fully_sampled = apps.mobafit(contrasts, M, iterations=STEPS, T2=80.0)

estimate = fully_sampled["T2"][support]
error = float((estimate - truth).norm() / truth.norm())
print(f"voxelwise fit, fully sampled: relative error {error:.3f}")
voxelwise fit, fully sampled: relative error 0.000
On the fully sampled echoes the voxelwise fit reaches a relative error far
below the two-step result on the undersampled data, of the same order as the
model-based fit. The fit itself is therefore not the limitation; the
undersampling artefacts of the echo images are. Try fitting the
undersampled echo images with more Gauss-Newton steps, or with fewer
echoes, for example images[:4] with a model built on the first four
echo times, and compare the errors.
As a spec#
What this lesson built, stated the way you would ask an agent for it:
Estimate a T2 map from an undersampled 2D multi-echo spin-echo scan with
bartorch: 8 echoes at TE = 12.5, 25, ..., 100 ms, 8 coils, 64x64 matrix,
R = 4 per echo with 8 central lines and a different random pattern per
echo. Encode with linop.CartesianSense over (echo, y, x) followed by a
linop.Diagonal of the patterns. Model the decay with
nlop.MultiEcho(TE, (64, 64)), starting at T2 = 80 ms. Compare (a) CG
(40 iterations) per echo followed by apps.mobafit, (b) nlop.IRGNM on
E @ M (20 steps, inner CG 100 iterations, tol 0.1), and (c) apps.moba
with the sensitivities and patterns (20 steps). Report the median and the
relative error of T2 inside the head, and show the maps and |error| maps.
References#
Total running time of the script: (0 minutes 35.468 seconds)