

Note
Go to the end to download the full example code.
Training without a reference#

The networks of lesson 11 and of Staged training of an unrolled network learn from fully sampled reference images. Dynamic and high-dimensional acquisitions – a cine, a functional run, a fingerprinting series – are rarely acquired fully sampled: undersampling is what makes them fit in a breath-hold or a scan time, so you have no reference to train against. In this tour you train the unrolled network of Staged training of an unrolled network from undersampled k-space alone and measure how much of the supervised network’s image quality it keeps.
The idea is self-supervised learning via data undersampling (SSDU) [1]: train against the measured k-space itself. You split the acquired phase encodes \(\Omega\) into two disjoint sets, \(\Theta\) and \(\Lambda\). The network reconstructs from \(\Theta\), and the loss compares the k-space of its reconstruction with the measured data on the held-out set \(\Lambda\),
where \(A_\Lambda\) is the SENSE encoding restricted to \(\Lambda\). A new split is drawn at every step, so over the training every acquired line is both reconstructed from and held out [2]. At inference the network reconstructs from all of \(\Omega\).
Prerequisites: lesson 11, 11. Training an unrolled network, and the tour Staged training of an unrolled network.
Learning objectives
Partition the acquired phase encodes with
bartorch.learning.split().Train an unrolled network self-supervised with
bartorch.learning.Reconstruction, by giving items the sampling pattern instead of a reference.Compare with the same network trained against references, and with CG-SENSE.
Data#
You use the slices, coils and fourfold undersampling of Staged training of an unrolled network: BrainWeb [3] subject 0 to train on and subject 4 to validate on. The references stay here only to score the results; the self-supervised network never sees them.
import lightning
import torch

import bartorch
import bartorch.tools as bt

from bartorch import learning, linop, optim, priors
from monai.metrics import PSNRMetric, SSIMMetric
from torch.utils.data import DataLoader

COILS = 8
ITERATIONS = 4
ACCELERATION = 4
EPOCHS = 16
NOISE = 0.02

_ = torch.manual_seed(0)

train_images = brain_slices(subject=0, count=24)
valid_images = brain_slices(subject=4, count=8)

coils = bt.coils(t=bt.grid(D=(SIZE, SIZE, 1)), n=COILS)[:, 0]
sensitivities = coils / bartorch.rss(coils, axes=(0,), keepdim=True)

ky = torch.arange(SIZE) - SIZE / 2
density = torch.exp(-0.5 * (ky / (SIZE / 6)) ** 2)
chance = density / density.sum() * (SIZE / ACCELERATION)
draw = torch.rand(SIZE, generator=torch.Generator().manual_seed(1))
lines = draw < chance
lines[SIZE // 2 - 4 : SIZE // 2 + 4] = True
pattern = lines.to(torch.complex64)[:, None].expand(SIZE, SIZE).contiguous()
A = linop.CartesianSense(sensitivities, (SIZE, SIZE), pattern=pattern)

generator = torch.Generator().manual_seed(3)


def measure(x):
    noise = torch.randn(A.oshape, dtype=torch.complex64, generator=generator)
    return A(x) + NOISE * noise


kspace = {
    "train": [measure(x) for x in train_images],
    "valid": [measure(x) for x in valid_images],
}
Sample splitting#
The readout is fully sampled, so the unit of the split is the phase-encode
line: the pattern you give split() has one entry
per line and broadcasts over the coils and the readout. A quarter of the
acquired lines are held out, drawn with a Gaussian density across
\(k_y\), and the eight central lines always stay in \(\Theta\). A
reconstruction without the centre of k-space would lose the image contrast,
and the loss would be dominated by it.
acquired = lines.float()[:, None]
split_seed = torch.Generator().manual_seed(0)
keep, held = learning.split(acquired, 0.25, keep=(8, 1), generator=split_seed)
print(
    f"{int(acquired.sum())} acquired lines: {int(keep.sum())} to reconstruct "
    f"from, {int(held.sum())} held out"
)
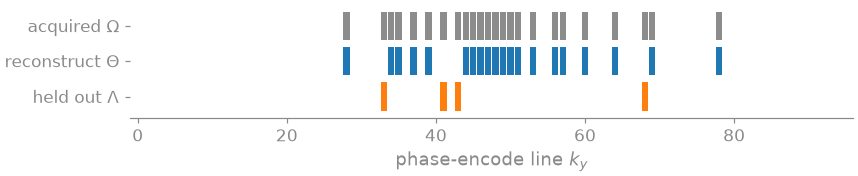
24 acquired lines: 20 to reconstruct from, 4 held out
Of the 24 acquired lines, 20 are kept for the reconstruction and 4 are held out. The eight central lines are in \(\Theta\) in every split, and the held-out lines are drawn from the acquired lines outside them.
Supervised and self-supervised training#
Both are the iteration-conditioned unrolled network of
Staged training of an unrolled network, trained end to end for the same number of epochs
from the same initialization; only the items differ. A self-supervised item
carries the acquired pattern in place of a target, and
Reconstruction then draws a split at every step.
Its validation loss is the held-out loss on a split fixed for the whole run,
and needs no reference either.
def unrolled():
    torch.manual_seed(0)
    network = learning.UNet(2, spatial=2, widths=(16, 32, 64), steps=True)
    denoiser = learning.ComplexNet(network, spatial=2)
    block = optim.ISTBlock(priors.ImplicitPrior(denoiser, step=True), step=1.0)
    block.step.requires_grad_()
    return learning.Unrolled(block, iterations=ITERATIONS, checkpoint=True)


def items(part, supervised):
    images = train_images if part == "train" else valid_images
    made = []
    for x, y in zip(images, kspace[part]):
        item = {"y": y, "A": A}
        if supervised:
            item["target"] = x
        else:
            item["pattern"] = acquired
        made.append(item)
    return made


models = {}
for name, supervised in (("supervised", True), ("self-supervised", False)):
    models[name] = unrolled()
    trainer = lightning.Trainer(
        max_epochs=EPOCHS,
        accelerator="cpu",
        logger=False,
        enable_checkpointing=False,
        enable_model_summary=False,
        enable_progress_bar=False,
    )
    stage = learning.Reconstruction(
        models[name],
        "end-to-end",
        lr=1e-3,
        fraction=0.25,
        split_options={"keep": (8, 1)},
    )
    trainer.fit(
        stage,
        DataLoader(
            items("train", supervised),
            batch_size=4,
            shuffle=True,
            collate_fn=list,
        ),
        DataLoader(items("valid", supervised), batch_size=4, collate_fn=list),
    )
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/lightning/pytorch/utilities/_pytree.py:21: `isinstance(treespec, LeafSpec)` is deprecated, use `isinstance(treespec, TreeSpec) and treespec.is_leaf()` instead.
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:434: The 'val_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=3` in the `DataLoader` to improve performance.
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:434: The 'train_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=3` in the `DataLoader` to improve performance.
Results#
Both networks reconstruct from all acquired lines of the validation subject, and you score them, and CG-SENSE, against its reference:
psnr = PSNRMetric(max_val=1.0)
ssim = SSIMMetric(spatial_dims=2, data_range=1.0)
truth = torch.stack(valid_images).abs()[:, None]


def quality(images):
    made = images.abs()[:, None]
    return float(psnr(made, truth).mean()), float(ssim(made, truth).mean())


results = {}
with torch.no_grad():
    for name, model in models.items():
        results[name] = torch.stack([model(y, A) for y in kspace["valid"]])
results["CG SENSE, 20 iterations"] = torch.stack(
    [optim.cg(y, A, maxiter=20) for y in kspace["valid"]]
)
             supervised   PSNR 30.16 dB   SSIM 0.950
        self-supervised   PSNR 28.59 dB   SSIM 0.726
CG SENSE, 20 iterations   PSNR 24.27 dB   SSIM 0.558
Both networks score well above CG-SENSE, and the supervised one scores above the self-supervised one in PSNR and, by a wider margin, in SSIM. The self-supervised network is trained on less information: each step reconstructs from three quarters of the acquired lines and receives no signal about the lines never acquired, which is where the supervised network learns most. The gap between the two is what a fully sampled reference adds; the self-supervised network needs nothing beyond the data the protocol already acquires.
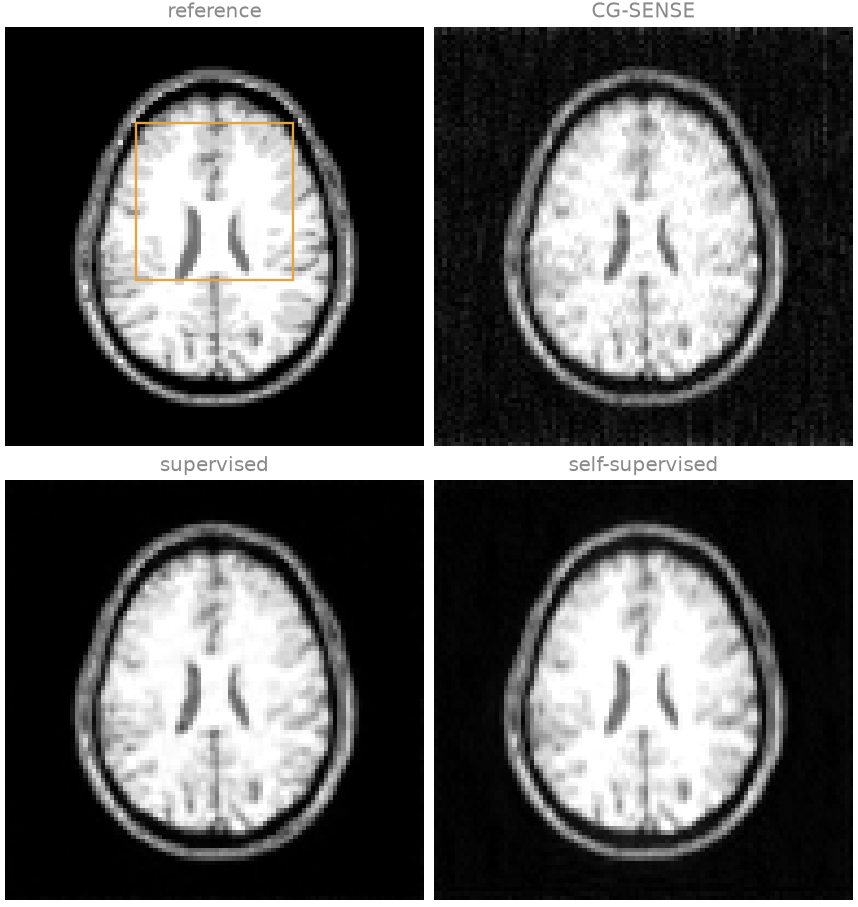
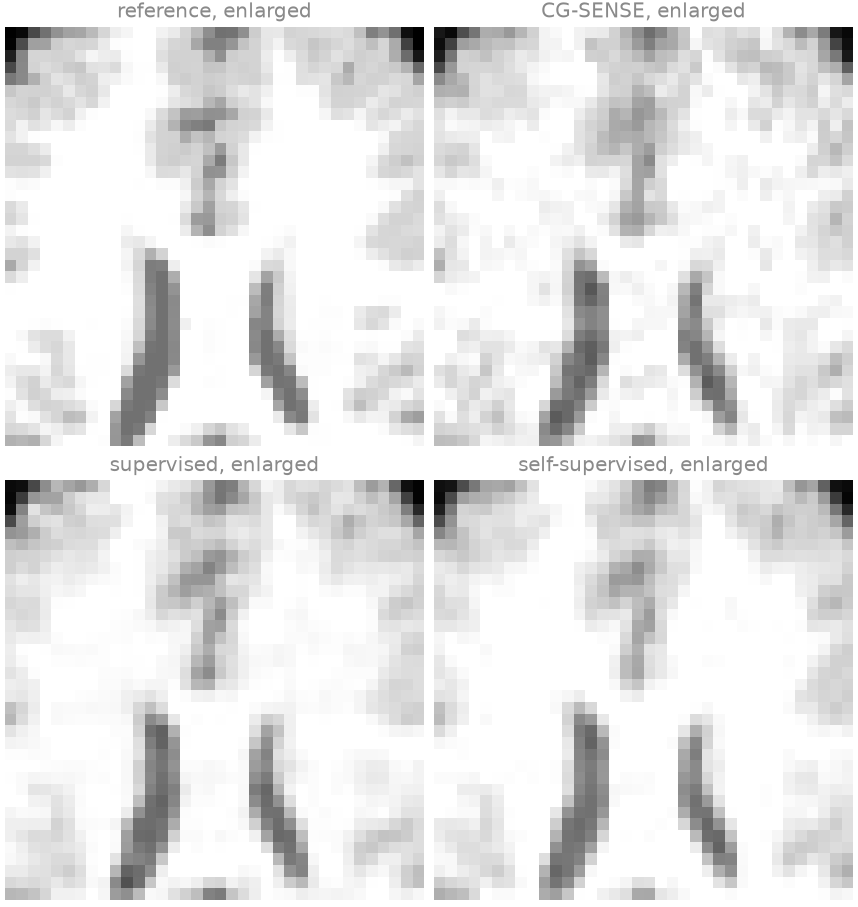
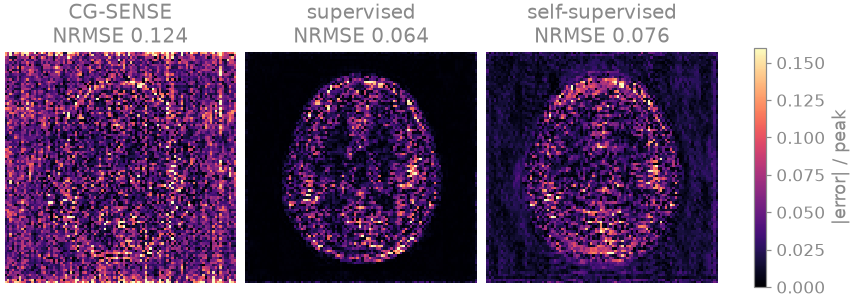
Both networks suppress the noise that the CG-SENSE unfolding amplifies across the whole field of view. The self-supervised error map keeps more residual structure, including faint horizontal bands that extend outside the head: aliasing along the phase-encode direction (vertical) from the lines never acquired, against which the self-supervised loss has no data to compare.
Exercise: held-out fraction#
During training the self-supervised network only ever reconstructs from \(\Theta\). Reconstruct the validation slices from the \(\Theta\) of the split above, without the held-out quarter, and compare with the full \(\Omega\). No training is involved:
subset = linop.CartesianSense(
    sensitivities, (SIZE, SIZE), pattern=(pattern * keep).to(torch.complex64)
)
from_theta = {}
with torch.no_grad():
    for name, model in models.items():
        made = [model(y * keep, subset) for y in kspace["valid"]]
        from_theta[name] = torch.stack(made)
     supervised: PSNR 30.16 dB from Omega, 27.53 dB from Theta
self-supervised: PSNR 28.59 dB from Omega, 27.90 dB from Theta
Without the held-out quarter both networks lose PSNR, the supervised one by about 2.7 dB and the self-supervised one by under 1 dB, so that the self-supervised network is now the better of the two. It was trained on inputs with that sampling; the supervised network was trained on all of \(\Omega\) and has not seen an input with these lines missing.
As a spec#
What this tour built, stated the way you would ask an agent for it:
Train the 4-iteration unrolled ISTA network of the staged-training tour
(UNet(2, spatial=2, widths=(16, 32, 64), steps=True), learned step) on
2D Cartesian SENSE data (8 coils, R = 4, 8 central lines, noise 0.02)
twice with learning.Reconstruction(..., "end-to-end", lr=1e-3), 16
epochs each: supervised, with a "target" per item, and self-supervised
(SSDU), with the acquired line "pattern" per item, fraction=0.25 and
split_options={"keep": (8, 1)}. Reconstruct the validation subject from
all acquired lines and report PSNR and SSIM of both and of CG-SENSE.
References#
Total running time of the script: (4 minutes 5.372 seconds)