learning.Unrolled#
- class bartorch.learning.Unrolled#
Bases:
ModuleUnrolled network: an iteration block applied a fixed number of times.
With every parameter frozen the stack reproduces the corresponding solver bit for bit;
requires_grad_()on a step size, a penalty weight or a denoiser’s weights makes it trainable. One block shared by every iteration shares the weights; a sequence of blocks gives each iteration its own. MoDL is anADMMBlockwhose single term is anImplicitPrior.detachandcheckpointselect the backward pass without changing the value computed:by default the whole stack is recorded, and memory grows with the number of iterations;
detach=Truestarts each iteration from a detached state; with a loss on each imagesteps()yields, this is greedy per-iteration training, with memory independent of the number of iterations;checkpoint=Truekeeps the states between iterations and recomputes each step in the backward pass, giving the end-to-end gradient at the cost of a second application of every block.
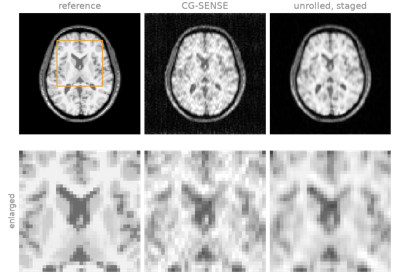
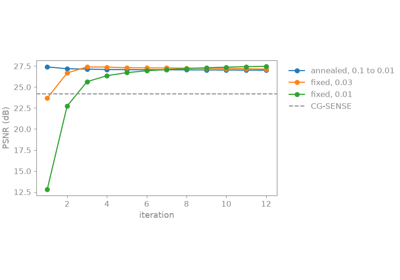
bartorch.optim.FixedPointis the alternative without an iteration count, differentiated at the fixed point. Learned reconstruction compares the strategies.- Parameters:
block (nn.Module or sequence of nn.Module) – One of
bartorch.optim’s iteration blocks, or one per iteration.iterations (int, default=None) – Number of applications of a shared block; the sequence’s length for a sequence.
detach (bool, default=False) – Start each iteration from a detached state.
checkpoint (bool, default=False) – Recompute each iteration in the backward pass rather than store it.
- Raises:
ValueError – A shared block without
iterations, an empty sequence, aniterationsthat differs from the sequence’s length, or fewer than one iteration.
Notes
A checkpointed step is correct only if its recomputation reproduces it. PyTorch’s random state is restored for the recomputation, so dropout is reproduced; a BART term that draws random shifts from BART’s generator, such as
WaveletorLocallyLowRankwithrandshift=True, is not, and the gradient then does not belong to the forward pass. This is not checked.Examples
>>> block = optim.ADMMBlock(priors.ImplicitPrior(denoiser), rho=0.05, cg_maxiter=10)
>>> block.rho.requires_grad_()
>>> model = learning.Unrolled(block, iterations=10, checkpoint=True)
>>> model(kspace, A).abs().sub(target).square().mean().backward()
- block()#
The block applied at iteration
k.
- steps()#
Yield the image after each iteration.
Takes the arguments of
forward(). A loss on each yielded image, withdetach=True, is greedy per-iteration training.
- forward()#
Run the iterations and return the last image.
- Parameters:
y (torch.Tensor) – Data, with or without a leading batch axis.
A (LinearOperator) – Encoding operator, shared by every item of a batch.
x0 (torch.Tensor, default=None) – Starting image; zero when omitted, as in BART.
- Returns:
The image after the last iteration.
- Return type:
torch.Tensor