optim.ADMMBlock#
- class bartorch.optim.ADMMBlock#
Bases:
ModuleOne iteration of the alternating direction method of multipliers, BART’s
admm.For \(\min_x \tfrac12 \| A x - y \|^2 + \sum_j g_j(G_j x - b_j)\), a step solves the x-update \(\bigl(M (A^H A + \lambda) + \rho \sum_j G_j^H G_j\bigr) x = M A^H y + \rho \sum_j G_j^H (z_j - u_j + b_j)\) by conjugate gradients from the previous \(x\), then updates each term’s split \(z_j\) and scaled dual \(u_j\). The state’s
doneis the residual stopping test, andinvokescounts the conjugate-gradient iterations spent, the quantityADMM’smaxiterbudgets.- Parameters:
priors (Regularizer or ImplicitPrior, or an iterable of them) – The terms \(g_j\), with any transform \(G_j\).
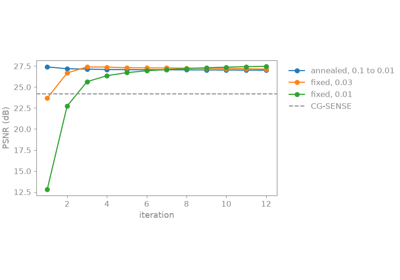
rho (float or sequence of float, default=0.5) – Penalty parameter \(\rho\). A sequence is a schedule, one value per iteration and the last repeated beyond its end; the scaled duals are rescaled at each change so the unscaled ones carry over (annealed plug-and-play, \(\rho_k = \lambda / \sigma_k^2\)).
alpha (float, default=1.6) – Over-relaxation parameter.
cg_maxiter (int, default=10) – Conjugate-gradient iterations per x-update.
cg_maxiter_first (int, default=None) – Conjugate-gradient iterations of the first x-update;
cg_maxiterwhen omitted.cclambda (float, default=0.0) – \(\lambda\), the weight of an identity added to the normal operator.
biases (sequence of tensor, default=None) – The \(b_j\), one per term, each of its term’s
prox_shape().dynamic_rho (bool, default=False) – Multiply \(\rho\) by
tauwhen the primal residual exceedsmutimes the dual, divide it in the opposite case.dynamic_tau (bool, default=False) – Set
taufrom the residuals, \(\sqrt{r / s}\) or its inverse, clipped totau_max.relative_norm (bool, default=False) – Compare the residuals each relative to its scaling.
fast (bool, default=False) – Skip the residuals and the stopping test.
hogwild (bool, default=False) – Double \(\rho\) after iteration 1, 3, 7, 15, …
mu (float, default=3.0) – Residual ratio beyond which
dynamic_rhorescales \(\rho\).tau_max (float, default=20.0) – Upper bound of
tau.abstol (float, default=0.0) – Absolute tolerance of the residual stopping test.
reltol (float, default=0.0) – Relative tolerance of the residual stopping test.
precond (LinearOperator, default=None) – Left preconditioner \(M\) from
A.ishapeto itself, positive definite (lsqr2_create’sprecond_op).
- Raises:
ValueError –
hogwildorfastwithdynamic_rho; arhoschedule withdynamic_rhoorhogwild; not one bias per term; atstart(), biases with a term with auxiliary variables.
Notes
With
dynamic_rhoorhogwildthe state carries \(\rho\). With a term that has auxiliary variables the state’sxis the image followed by those variables, andoutput()returns the image alone.- start()#
Initial state of a run.
- Parameters:
y (tensor) – Data of
A.oshape, or(batch, *A.oshape).A (LinearOperator) – Encoding operator.
x0 (tensor, default=None) – Starting image; zero when omitted, as in BART.
- Returns:
The start, zero splits and duals, and \(M A^H y\).
- Return type:
State
- forward()#
Take one iteration from
state; returns the next state.
- output()#
Image of
state, without any auxiliary variables.