

Note
Go to the end to download the full example code.
Uncertainty estimation#

A learned reconstruction returns an image without saying where it may be wrong. Where the undersampling leaves the image underdetermined, the network fills in what its training data suggest, and a hallucinated structure looks like real anatomy. In this tour you attach a voxel-wise error bar to the unrolled reconstruction of Staged training of an unrolled network, calibrate it so that it contains the true error in a stated fraction of voxels, and look at where in the head the reconstruction is least certain.
The method has two parts. First, you randomize the reconstruction and repeat it: leave dropout active in the network (Monte Carlo dropout [1]), reconstruct from random subsets of the acquired phase encodes, or shift a patch grid. The spread of the repeats measures one source of variability, and none of them is the error itself. Second, split conformal calibration [2] relates the spread to the error on held-out slices with fully sampled references: it finds the factor by which you must multiply the spread for the interval to contain the error at a chosen rate, a guarantee that holds whatever the spread measures.
Prerequisites: lesson 11, 11. Training an unrolled network, and the tour Staged training of an unrolled network.
Learning objectives
Obtain a spread from Monte Carlo dropout and from k-space subsets with
bartorch.learning.moments().Calibrate it to a coverage with
bartorch.learning.calibrate(), and check the coverage on other slices.Compare the calibrated interval with the error made.
Data#
You use the slices, coils and fourfold undersampling of Staged training of an unrolled network, with BrainWeb [3] subject 0 to train on and sixteen slices of subject 4: the first eight to calibrate on, the last eight to check the calibration on.
import lightning
import torch

import bartorch
import bartorch.tools as bt

from bartorch import learning, linop, optim, priors
from torch.utils.data import DataLoader

COILS = 8
ITERATIONS = 4
ACCELERATION = 4
EPOCHS = 8
DROPOUT = 0.1
NOISE = 0.02

_ = torch.manual_seed(0)

train_images = brain_slices(subject=0, count=24)
valid_images = brain_slices(subject=4, count=16)

coils = bt.coils(t=bt.grid(D=(SIZE, SIZE, 1)), n=COILS)[:, 0]
sensitivities = coils / bartorch.rss(coils, axes=(0,), keepdim=True)

ky = torch.arange(SIZE) - SIZE / 2
density = torch.exp(-0.5 * (ky / (SIZE / 6)) ** 2)
chance = density / density.sum() * (SIZE / ACCELERATION)
draw = torch.rand(SIZE, generator=torch.Generator().manual_seed(1))
lines = draw < chance
lines[SIZE // 2 - 4 : SIZE // 2 + 4] = True
pattern = lines.to(torch.complex64)[:, None].expand(SIZE, SIZE).contiguous()
A = linop.CartesianSense(sensitivities, (SIZE, SIZE), pattern=pattern)

generator = torch.Generator().manual_seed(3)


def measure(x):
    noise = torch.randn(A.oshape, dtype=torch.complex64, generator=generator)
    return A(x) + NOISE * noise


kspace = {
    "train": [measure(x) for x in train_images],
    "valid": [measure(x) for x in valid_images],
}
Monte Carlo dropout#
The network is the iteration-conditioned unrolled network of Staged training of an unrolled network, with dropout in every residual block of its U-Net, trained end to end against references. During training dropout is a regularizer; left active at inference it makes each reconstruction one draw from a family of networks.
torch.manual_seed(0)
network = learning.UNet(
    2,
    spatial=2,
    widths=(16, 32, 64),
    steps=True,
    dropout=DROPOUT,
)
prior = priors.ImplicitPrior(learning.ComplexNet(network, spatial=2), step=True)
block = optim.ISTBlock(prior, step=1.0)
block.step.requires_grad_()
model = learning.Unrolled(block, iterations=ITERATIONS, checkpoint=True)

pairs = {
    "train": zip(train_images, kspace["train"]),
    "valid": zip(valid_images[:8], kspace["valid"]),
}
train_items = [{"y": y, "A": A, "target": x} for x, y in pairs["train"]]
valid_items = [{"y": y, "A": A, "target": x} for x, y in pairs["valid"]]
trainer = lightning.Trainer(
    max_epochs=EPOCHS,
    accelerator="cpu",
    logger=False,
    enable_checkpointing=False,
    enable_model_summary=False,
    enable_progress_bar=False,
)
trainer.fit(
    learning.Reconstruction(model, "end-to-end", lr=1e-3),
    DataLoader(train_items, batch_size=4, shuffle=True, collate_fn=list),
    DataLoader(valid_items, batch_size=4, collate_fn=list),
)
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/lightning/pytorch/utilities/_pytree.py:21: `isinstance(treespec, LeafSpec)` is deprecated, use `isinstance(treespec, TreeSpec) and treespec.is_leaf()` instead.
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:434: The 'val_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=3` in the `DataLoader` to improve performance.
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:434: The 'train_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=3` in the `DataLoader` to improve performance.
Reconstruction spread#
moments() calls a randomized reconstruction a
number of times and returns the voxel-wise mean and variance. Your first
randomized reconstruction leaves the dropout modules in training mode and
everything else in evaluation mode:
The second keeps the network deterministic and reconstructs each time from a
random eighty per cent of the acquired lines, drawn by
split(). It measures how much the image depends on
individual samples.
acquired = lines.float()[:, None]


def from_a_subset(y):
    keep, _ = learning.split(acquired, 0.2, keep=(8, 1))
    kept = (pattern * keep).to(torch.complex64)
    subset = linop.CartesianSense(sensitivities, (SIZE, SIZE), pattern=kept)
    return model(y * keep, subset)


spreads = {}
for name, reconstruct in (
    ("dropout", with_dropout),
    ("k-space subsets", from_a_subset),
):
    means, deviations = [], []
    for y in kspace["valid"]:
        mean, variance = learning.moments(lambda: reconstruct(y), samples=8)
        means.append(mean)
        deviations.append(variance.sqrt())
    spreads[name] = (torch.stack(means), torch.stack(deviations))

truth = torch.stack(valid_images)
head = truth.abs() > 0.05
Calibration#
On the first eight slices, whose references you know,
calibrate() finds the factor that makes
|error| <= factor * spread hold for ninety per cent of the voxels in the
head. On the other eight you measure the fraction of voxels whose error
falls within factor * spread. Split conformal calibration guarantees
that fraction on average over voxels and subjects drawn alike, not voxel by
voxel.
COVERAGE = 0.9
calibration, test = slice(0, 8), slice(8, 16)


def calibrated(mean, deviation, coverage=COVERAGE):
    """The factor, and the coverage it reaches on the test slices."""
    error = (mean - truth).abs()
    on, off = head[calibration], head[test]
    factor = learning.calibrate(
        error[calibration][on],
        deviation[calibration][on],
        coverage,
    )
    inside = error[test] <= factor * deviation[test]
    return factor, float(inside[off].float().mean())
        dropout: factor   8.58, coverage 0.906 (asked 0.9), correlation of error and spread 0.26
k-space subsets: factor   3.82, coverage 0.897 (asked 0.9), correlation of error and spread 0.23
Both spreads reach close to 90 per cent coverage on the test slices, although their factors differ by more than a factor of two: the calibration absorbs whatever scale the spread has. What differs between them is how well the spread follows the error voxel by voxel, which the correlation measures and the maps below show. A spread that is large where the error is large gives narrow intervals where the reconstruction is reliable and wide ones where it is not; a spread unrelated to the error gives intervals of the right average width in the wrong places.
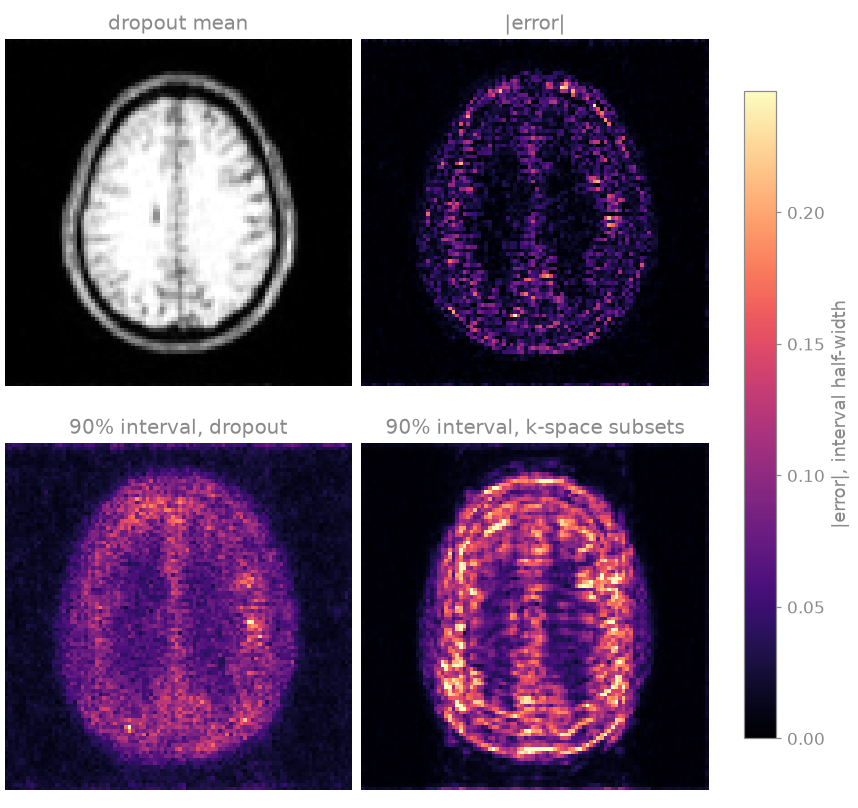
The two spreads measure different things. The dropout interval is diffuse over the brain and follows neither its anatomy nor the error. The k-space-subset interval is largest at the scalp and in horizontal bands, the pattern of aliasing along the phase-encode direction (vertical): removing lines moves the aliasing, and that is the variability it records. The error itself is concentrated in the cortex. Both correlations are weak, about 0.2, so the intervals are wider than the error over much of the white matter and narrower than it in parts of the cortex. The coverage holds on average over voxels, as the calibration guarantees, not voxel by voxel.
Exercise: target coverage#
The calibration works for any coverage you ask for. Calibrate the k-space-subset spread at 50, 80 and 95 per cent and check what the test slices reach; nothing is reconstructed again:
mean, deviation = spreads["k-space subsets"]
for coverage in (0.5, 0.8, 0.95):
    factor, reached = calibrated(mean, deviation, coverage)
    print(f"asked {coverage:.2f}: factor {factor:5.2f}, reached {reached:.3f}")
asked 0.50: factor  1.36, reached 0.506
asked 0.80: factor  2.70, reached 0.794
asked 0.95: factor  5.17, reached 0.951
The coverage reached on the test slices follows the one asked for at every level, and the factor grows with it: the calibration is a quantile of the ratio of error to spread on the calibration slices, read off at the level you ask for.
As a spec#
What this tour built, stated the way you would ask an agent for it:
Train the 4-iteration unrolled ISTA network of the staged-training tour
with dropout 0.1 in its UNet, end to end for 8 epochs, on 2D Cartesian
SENSE data (8 coils, R = 4, noise 0.02). On 16 test slices, compute a
voxel-wise mean and standard deviation with learning.moments over 8
draws, twice: with only the dropout modules in training mode, and from
random 80 per cent subsets of the acquired lines (learning.split, 8
central lines kept). Calibrate each with learning.calibrate to 90 per
cent coverage of the head voxels on the first 8 slices, and report the
coverage reached on the other 8 and the error-spread correlation.
References#
Total running time of the script: (1 minutes 37.151 seconds)